Author: Y. Y.

  • [Science] Why Letting AI Help Can Erode Your Grit, Berkeley Study Finds

    [Science] Why Letting AI Help Can Erode Your Grit, Berkeley Study Finds

    A chatbot that hands you the answer can make a hard problem feel easy — until the chatbot is gone. A new study from researchers at five universities found that people who solved problems with an AI assistant performed worse on the next problems, once that assistant was taken away, than people who had worked through the very same problems alone from the start. The gap showed up after roughly 10 to 15 minutes of AI-assisted problem-solving, and it held across three separate experiments involving 1,222 recruited participants — a pattern the authors say raises real questions about whether leaning on AI for answers can undermine people’s ability, or willingness, to solve problems on their own.

    Three Experiments, One Pattern

    The team — Grace Liu, Brian Christian, Tsvetomira Dumbalska, Michiel A. Bakker and Rachit Dubey, drawing on UC Berkeley’s Center for Human-Compatible AI along with Carnegie Mellon University, MIT, the University of Oxford and UCLA — ran three randomized controlled trials totaling 1,222 recruited participants (307, 585 and 168 after some participants were excluded under the researchers’ prespecified criteria). In the first experiment, 354 people were recruited to solve 12 basic fraction problems; half worked alone throughout, while the other half could ask a ChatGPT assistant, built on GPT-5, for help — before everyone, AI group included, had to solve three further problems entirely on their own. A second experiment repeated that design with 667 people, and a third, with 201 participants, swapped the math problems for SAT-style reading comprehension questions.

    In every version of the study, the early pattern looked encouraging: while they still had access to the AI, the assisted group solved problems faster and scored higher than the group working alone — exactly what you would expect from a capable assistant. The twist came in the second half of each session, once the AI was removed and everyone, including the AI group, had to finish the rest of the problems unaided.

    The Numbers Behind the Finding

    Once AI access ended, the previously assisted group fell behind the group that had never used it, and the gap was consistent across all three experiments. In the first fraction experiment, the former AI group answered an average of 57% of the three final problems correctly, versus 73% for the no-AI group — a statistically significant difference (p < 0.001). The larger replication of the same design found a smaller but still reliable gap: 71% versus 77% (p = 0.02). In the reading-comprehension experiment, the difference widened again, to 76% versus 89% (p = 0.007).
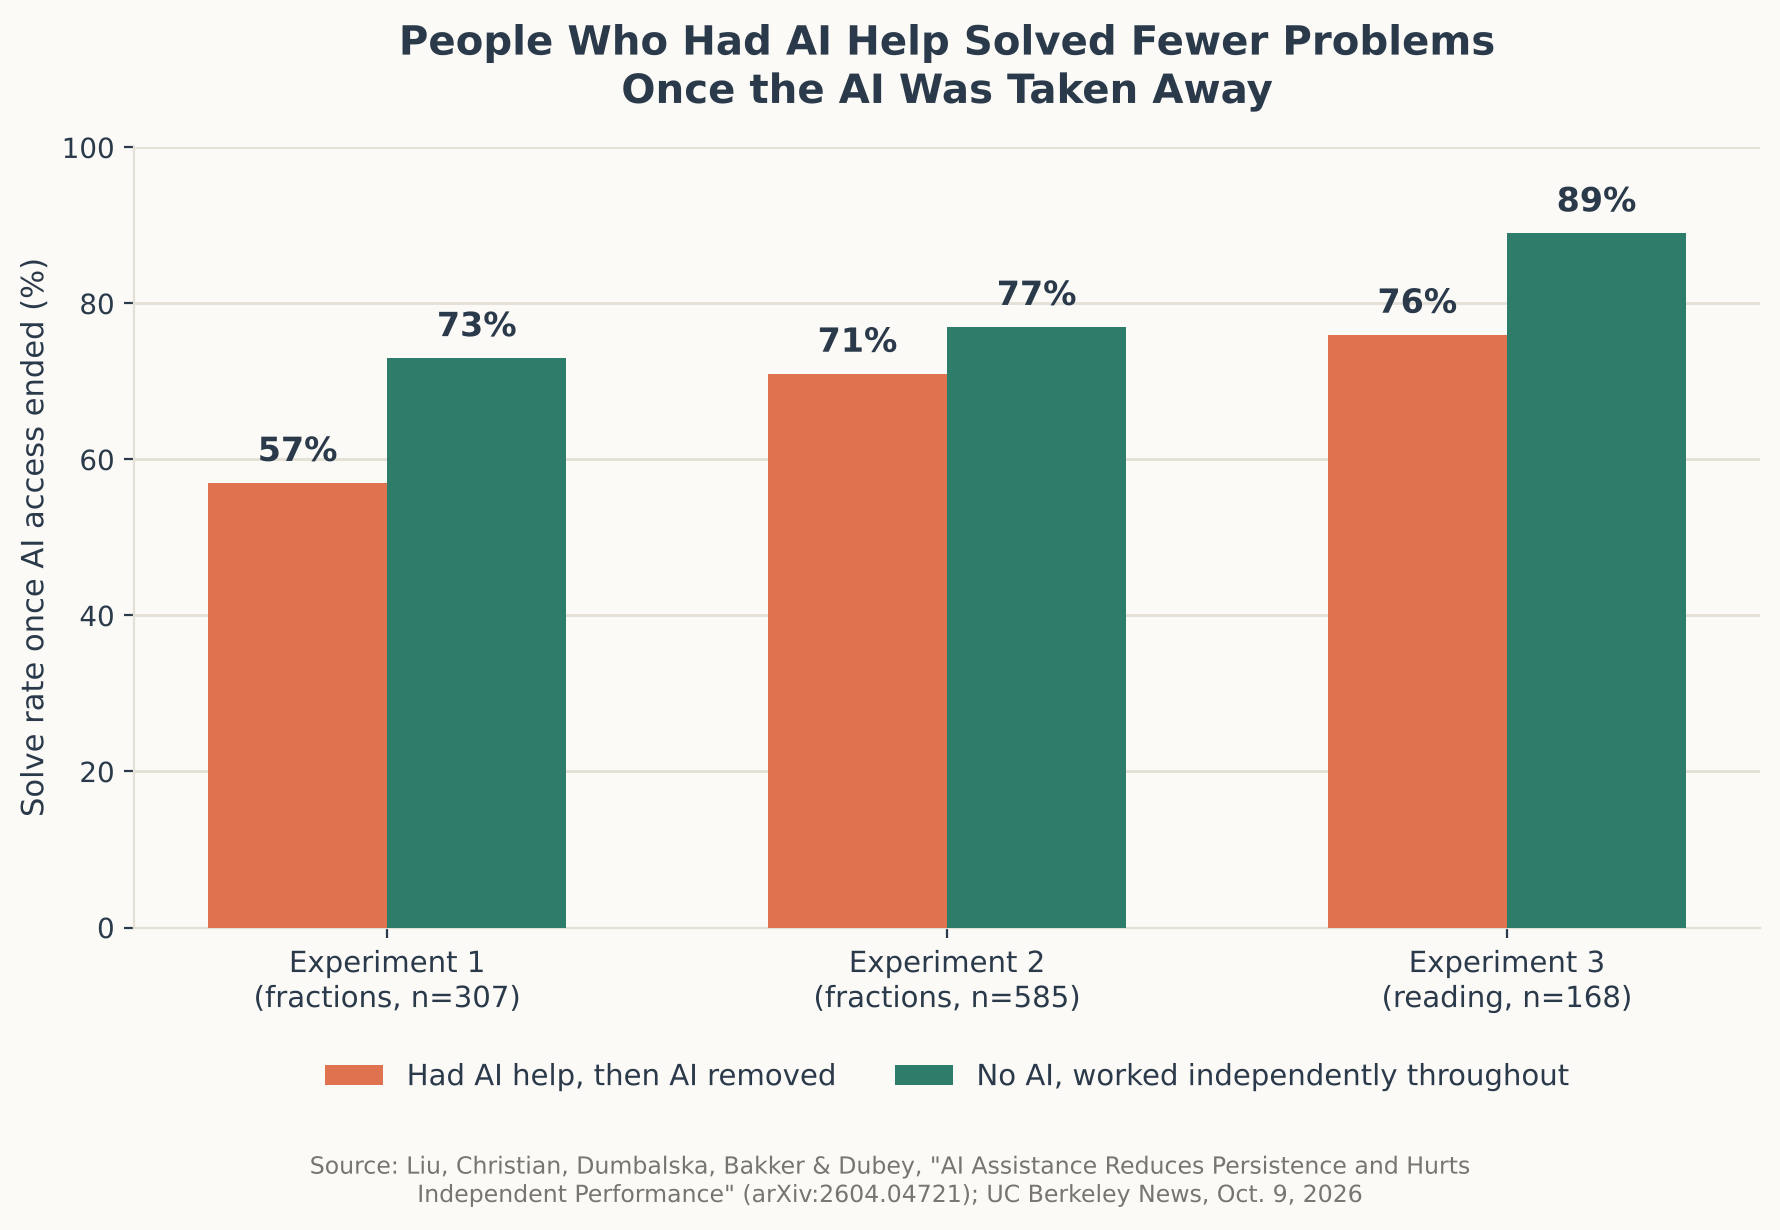
    Bar chart comparing solve rates after AI was removed across three experiments
    Source: data from Liu, Christian, Dumbalska, Bakker & Dubey (arXiv:2604.04721) and UC Berkeley News

    Giving up altogether followed a similar trend. In the first experiment, 20% of the former AI group skipped a problem rather than attempt it, compared with 11% of the no-AI group. The pattern was weaker in the larger replication (10% versus 7%, not statistically significant) but reappeared clearly in the reading task, where 8% of the AI group skipped questions versus just 1% of the control group. A closer look at how participants said they had actually used the AI while it was available sharpened the picture further, though this part of the analysis was observational rather than randomized, since people were not assigned to copy answers or ask for hints: those who reported simply copying the AI’s finished answers fared worst afterward, averaging just 65% correct on their own, while those who said they used the AI mainly for hints showed no statistically significant gap from people who never touched AI at all.

    Participants were randomly assigned to the AI or no-AI condition, and the larger replication added a pretest to check the groups further: accuracy and the tendency to skip a problem did not differ significantly between groups beforehand, which strengthens the case that the later gap reflects the AI condition itself rather than pre-existing differences between participants. In that same larger replication, participants were also asked how they had actually used the AI while it was available. A small slice, about 12%, said they had barely used it despite having access, and this group performed about as well afterward as people who never had AI access at all — reinforcing the idea that it is the degree of reliance on AI, not mere availability of it, that predicts the later drop-off.

    “It’s a striking finding, but in a way it supplies ammunition for a story that a lot of us kind of feel in our gut.” — Brian Christian, UC Berkeley

    What Might Explain the Pattern

    The authors propose two explanations, while cautioning that their experiments were not designed to prove which one is doing the work. The first is a kind of expectation mismatch: once someone gets used to near-instant answers, grinding through a problem by hand can suddenly feel disproportionately slow, which may make people more willing to give up rather than push through. The second is the loss of what the researchers call “productive struggle” — the idea that difficulty itself is not simply an obstacle to route around, but part of how people practice and strengthen the skills a problem requires. Bypass that effort often enough, the argument goes, and there may be fewer chances for those skills to get built in the first place.

    It’s a different mechanism, but this study joins a related question this site has covered before: Georgetown University researchers recently found that AI-generated summaries of events can distort people’s memory of what actually happened. That study is about memory rather than problem-solving, but together the two point to a broader pattern worth watching — handing a mental task to AI can carry a hidden cost to accuracy or independent ability, even when it feels like pure convenience in the moment.

    “Not Just Fractions and SAT Problems”

    Christian has been blunt about how far he thinks the implications reach beyond a psychology lab. “This is not a story about fractions and SAT problems,” he said in comments accompanying the study’s release. “This is something that is happening to human knowledge and human expertise.” He described the irony directly: widely used AI assistants, he said, are “often helping us in ways that are kind of unhelpful” — lifting performance on the task directly in front of us while, the data suggest, working against the independent competence we will need the next time no AI is around.

    The caveats matter here. The study measured performance minutes after AI access ended, not months or years later, so it cannot say how long this effect lasts or whether frequent users eventually adapt and recover. The breakdown by how people used the AI — copying answers versus asking for hints — was observational rather than randomized, so it shows an association rather than definitive proof of cause and effect. And all three experiments involved short, one-off tasks completed by paid online participants, a different setting from a student using AI across a semester of coursework or an employee weaving it into daily work.

    What This Means for Using AI

    None of this is an argument for avoiding AI assistance altogether — the same data show it clearly boosted short-term performance while it was available, and for many real-world tasks, getting the right answer quickly is exactly the point. The more useful takeaway from this one study may be about how AI gets used rather than whether: in the self-reported usage data, the steepest drop-off belonged to people who let the AI hand them a finished answer, while those who said they used it mainly for hints or partial guidance looked much closer to the group that never used AI at all. Treating a chatbot more like a tutor that nudges you toward a solution, rather than a vending machine that dispenses the finished one, looks like a reasonable bet for keeping your own problem-solving sharp — though it’s one study, in a narrow setting, and confirming how far that advice travels beyond fractions and reading quizzes will take further research.

    Sources: UC Berkeley News, arXiv:2604.04721, “AI Assistance Reduces Persistence and Hurts Independent Performance”
  • [Science] Earth’s Climate Indicators Hit Record Extremes in 2026 as Warming Speeds Up

    [Science] Earth’s Climate Indicators Hit Record Extremes in 2026 as Warming Speeds Up

    A new annual climate report finds that seven of Earth’s sixteen tracked climate indicators, including ocean heat, sea level, and ice loss, have reached record extremes in 2026. Just as notable, the authors estimate that the rate of global surface warming has climbed sharply over the past few decades. The findings matter well beyond climate science circles: if the recent pace continues, warming thresholds long treated as distant milestones could arrive within the working lifetime of people reading this, not generations from now.

    The Planet, Checked Like a Patient

    The findings come from “The 2026 State of the Climate Report: Challenges and Opportunities,” published on October 14, 2026 in the peer-reviewed journal BioScience. It is the latest edition of an annual series led by William Ripple, a distinguished professor at Oregon State University’s College of Forestry, and Christopher Wolf of Terrestrial Ecosystems Research Associates, with co-authors including climate scientist Michael Mann of the University of Pennsylvania and Johan Rockström of the Potsdam Institute for Climate Impact Research.

    The authors track sixteen “planetary vital signs” to monitor changes in Earth’s climate system. These include atmospheric greenhouse gas concentrations, global surface temperature, ocean heat content (the total heat stored in ocean water, including far below the surface, not just sea-surface temperature), sea level, and ice loss. Alongside these, they track the human activities behind the changes, such as fossil fuel consumption and the growth of renewable energy. Much as a doctor reads blood pressure or heart rate over time rather than relying on one measurement, the point of this framework is to follow a consistent set of numbers year after year, rather than judging the climate by any single dramatic event.

    Record Extremes and a Faster Warming Rate

    Of the sixteen indicators, seven, or 44 percent, are now at record extremes. Atmospheric carbon dioxide exceeded 428 parts per million (meaning about 428 CO₂ molecules per million molecules of dry air) in May 2026, roughly 50 percent above pre-industrial levels. Methane and nitrous oxide, two other greenhouse gases, also reached record levels based on year-to-date 2026 averages, though as the year is not yet complete, these figures remain provisional.

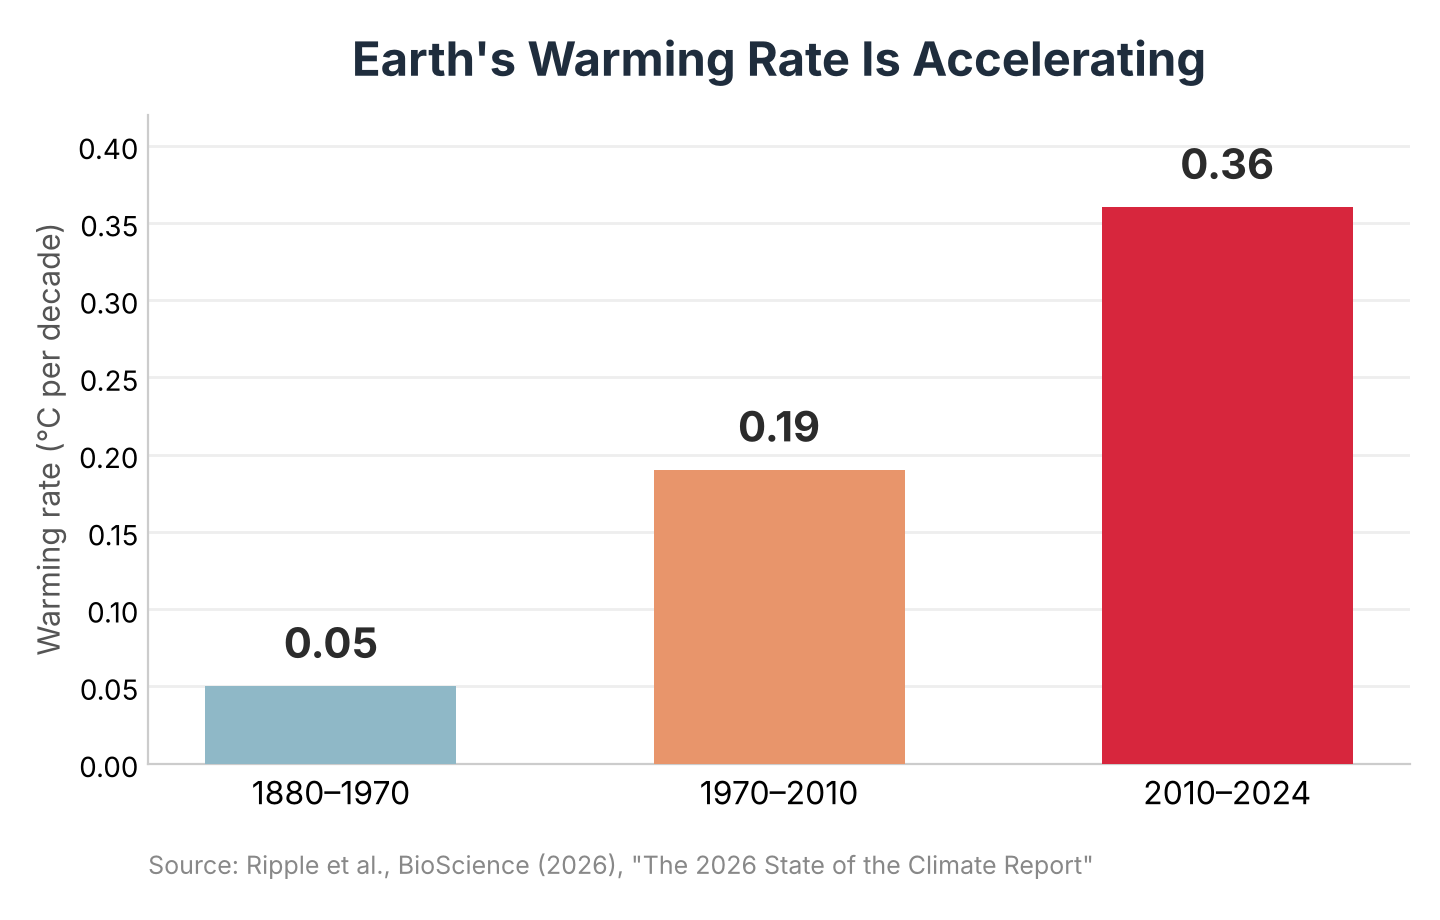
    The report’s warming-rate estimate is one of its most discussed figures. Using a segmented trend analysis, the authors put the rate of global surface warming at roughly 0.05 degrees Celsius per decade between 1880 and 1970, rising to about 0.19 degrees per decade between 1970 and 2010, and then to about 0.36 degrees per decade between 2010 and 2024. That is roughly seven times the earliest rate, though comparing periods of such different lengths calls for some caution: the most recent interval spans only 14 years, so it is more exposed to short-term swings such as El Niño than the 90-year span at the start of the record. Even allowing for that, the direction, a clearly faster recent pace, is consistent across the three periods. If this recent rate were to persist, the authors warn, warming could pass 2 degrees Celsius above pre-industrial levels before 2050; that is a conditional extrapolation from the observed trend, not a guaranteed forecast, since both natural variability and future policy choices could shift it either way.

    The rate of global surface warming rose from about 0.05°C per decade before 1970 to about 0.36°C per decade since 2010 — roughly seven times faster.
    Bar chart showing global warming rate rising from 0.05 to 0.19 to 0.36 degrees Celsius per decade across three periods
    Source: Ripple et al., BioScience (2026), “The 2026 State of the Climate Report”

    The authors describe several indicators as showing accelerating trends or abrupt shifts that could make some future changes harder to anticipate than the steadier patterns of past decades.

    Oceans and Ice Absorb the Impact

    Much of the planet’s response to rising greenhouse gases plays out beneath the ocean surface rather than in the air people breathe. The report finds ocean heat content and global sea level at record highs, while glacier thickness and the mass of the Greenland ice sheet sit at record lows. Energy-related carbon dioxide emissions, meanwhile, passed 41 gigatons for the first time in 2025.

    The overall trend is clear, although scientists continue to refine how they measure ocean heat uptake region by region. A separate study published this month by researchers at the University of Bonn combined satellite and ocean-float data to estimate how much heat different ocean basins are absorbing. For the Indian Ocean during 2005–2015, the new estimate came in at 0.58 watts per square meter, against 1.09 watts per square meter from a commonly used climate reanalysis dataset, ORAS5, a nearly two-fold gap for that basin and period specifically. Xsciens covered that study in more detail here. The gap does not overturn the broader picture that oceans are absorbing most of Earth’s excess heat; it is a reminder that even well-established indicators like ocean heat content keep being refined as measurement methods improve.

    Glaciers are a visible, land-based counterpart to that underwater story. Switzerland’s glacier monitoring network reported that Swiss glaciers lost roughly 5.5 percent of their ice volume in 2026, the second-largest annual loss on record after 2022, a sign that frozen water reserves relied on for seasonal water supply are shrinking at a pace that leaves less room for error in regional water planning.

    The Human Toll, and How to Read It

    The report documents a series of disasters from the past year that illustrate the human costs of extreme weather. Hurricane Melissa, which struck the Caribbean in October 2025, caused 95 deaths and more than 12 billion dollars in damage. A separate storm in November 2025, combined with monsoon flooding in Indonesia, killed 708 people. A June 2026 heatwave across Europe is associated, in a preliminary statistical estimate, with around 14,000 excess deaths, meaning deaths above the number that would normally be expected, calculated from mortality data and a model rather than counted individually; the figure is not yet finalized and could be revised.

    The report’s authors write that these events “were at least partly attributable to climate change,” a deliberately qualified statement: it does not claim that any single storm or heatwave would have been impossible without global warming, but that warming is believed to have raised the odds or intensity of each one to some degree. That is consistent with how formal event-attribution science generally works, comparing the likelihood of an event in today’s warmer climate against a hypothetical world without human-caused warming, rather than issuing a simple yes-or-no verdict.

    Beyond individual disasters, the authors flag rising risk around climate “tipping points”: thresholds beyond which feedbacks could drive changes that become difficult, or in some cases effectively impossible, to reverse on human timescales. Two examples they highlight are a weakening of the Atlantic Meridional Overturning Circulation, the ocean current system that helps regulate temperatures across the North Atlantic region, and the risk of large-scale Amazon rainforest dieback, which the report suggests could be triggered by the combined effects of warming and deforestation at as little as 1.5 to 1.9 degrees Celsius of warming. The authors describe continued warming and interacting feedbacks as raising the risk of a self-reinforcing “hothouse” trajectory, marked by weakening natural carbon sinks and accelerating ice loss, though they present this as an elevated risk worth monitoring closely, not an outcome they predict is imminent.

    A Mixed Picture on Energy

    The report is not uniformly bleak. Low-carbon energy sources collectively supplied about 43 percent of global electricity in 2025, and solar and wind consumption grew by roughly 18 percent over the previous year. For the first time in more than a century, renewable energy sources globally surpassed coal as an electricity source. Battery storage, which helps make intermittent solar and wind power more usable around the clock, is also expanding quickly.

    Yet the authors are blunt that this progress remains far short of what is needed. Global fossil fuel consumption still rose by 0.9 percent in 2025, because rising overall energy demand has outpaced the growth of clean alternatives rather than being displaced by them. On adaptation, the gap is starker still: the report cites roughly 64 billion dollars in international public adaptation finance reaching developing countries in 2024, against an estimated need of 310 to 365 billion dollars per year by 2035.

    What the Report Recommends

    The authors call for pursuing rapid cuts to greenhouse gas emissions alongside faster investment in adaptation and resilience, rather than treating the two as separate tracks. They point to measures such as mangrove and wetland restoration, which both protect coastlines and store carbon, early warning systems for extreme weather, and a stronger emphasis on climate justice so that adaptation funding reaches local and frontline communities rather than only large infrastructure projects. They also point to interactive public tools, such as the En-ROADS climate simulator and the Drawdown Explorer, for evaluating the trade-offs between different policy choices.

    The report does not predict inevitable catastrophe. It documents a climate system under increasing, and in some respects accelerating, pressure, while pointing to specific areas where policy and technology can still change the trajectory. Its underlying message is less a single verdict than a status update: of sixteen vital signs checked in 2026, seven are flashing red, the pace of change is quickening, and the choices made over the next few years will help determine how many more join them.

    Sources: American Institute of Biological Sciences / EurekAlert, Ripple et al., “The 2026 State of the Climate Report,” BioScience (2026), University of Bonn, GPB/NPR on Swiss glacier loss

  • [Science] A Retinal Chip Restores Reading Vision in Macular Degeneration — Gains Hold 3 Years Later

    [Science] A Retinal Chip Restores Reading Vision in Macular Degeneration — Gains Hold 3 Years Later

    A chip about the size of a pinhead, implanted beneath the retina, is still giving some people with an advanced, largely untreatable form of vision loss enough artificial central vision to read letters and words three years after surgery. New follow-up data from the PRIMA retinal implant, presented in a late-breaking session at a major European retina congress and discussed at the American Academy of Ophthalmology’s 2026 annual meeting, suggest that the vision gain patients saw in year one did not fade by year three — it grew slightly instead, an encouraging early sign for a disease that otherwise only gets worse with time, even if the follow-up group is still small.

    Illustration of an eye with a microchip implant
    Illustration: an artificial retinal implant restores light sensitivity where photoreceptor cells have died.

    What the Three-Year Data Show

    The results come from PRIMAvera, a clinical trial that implanted the PRIMA device in 38 people across 17 centers in five European countries, all diagnosed with geographic atrophy, the advanced form of age-related macular degeneration that destroys central vision. The trial had no control group, so every participant received the implant. At the start of the study, their average vision was about 20/460, meaning they could not reliably make out even the largest letter on a standard eye chart.

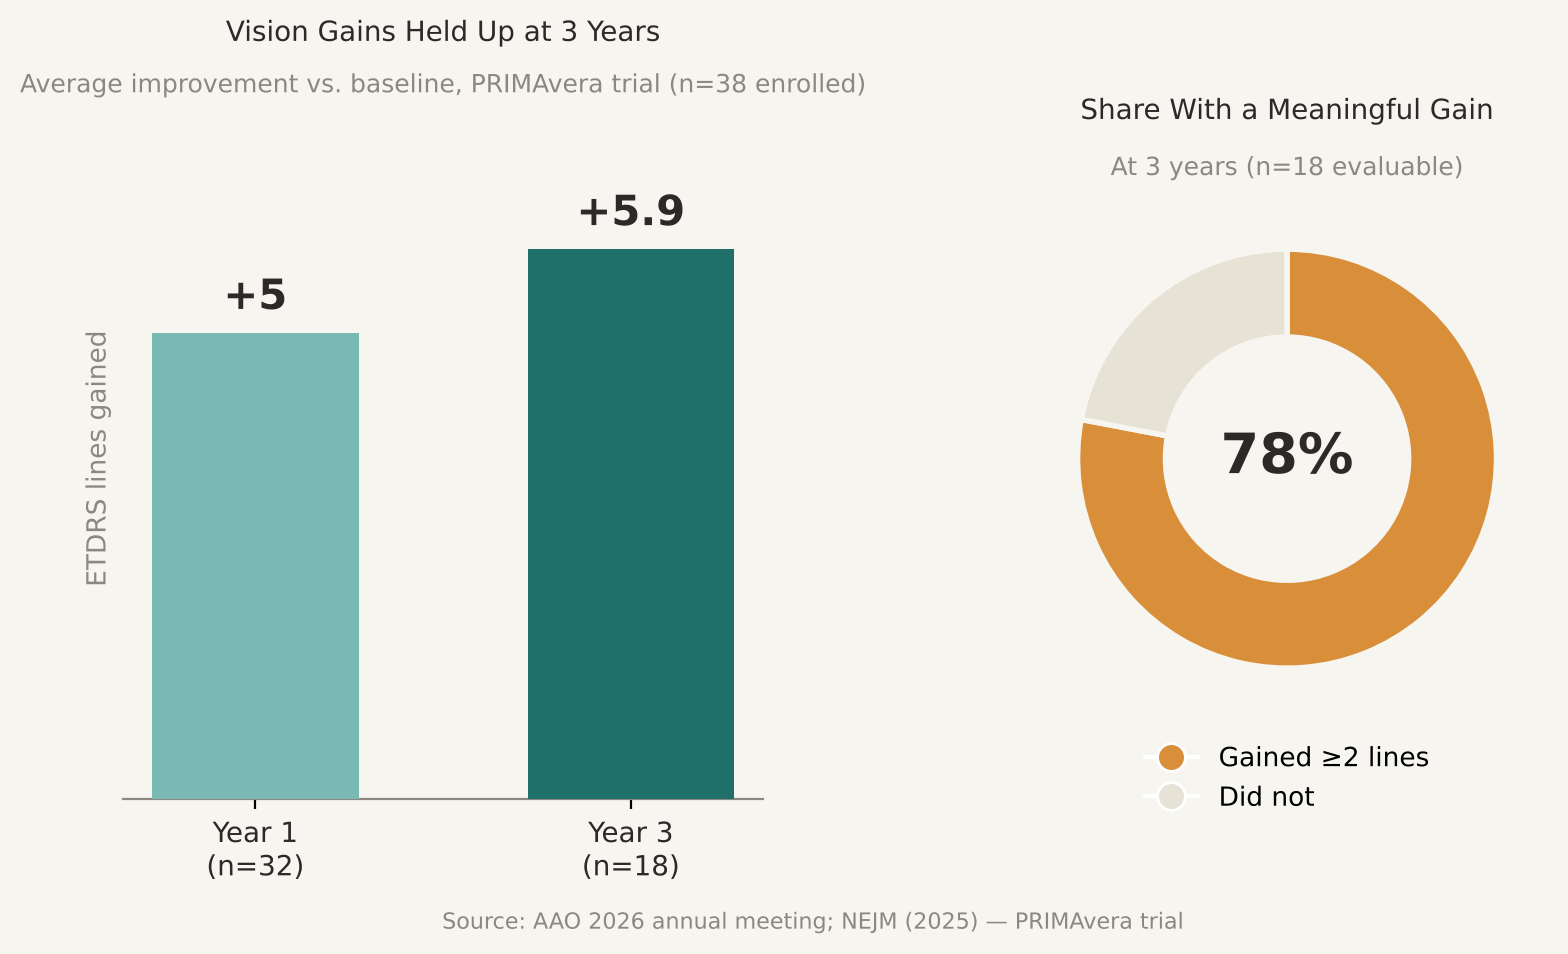
    At 12 months, 32 of the 38 implanted participants were evaluable, and their eyes had gained an average of 24.5 letters on a standard vision chart, roughly five lines, a result published in a peer-reviewed paper in The New England Journal of Medicine. At 36 months, among the 18 participants still evaluable for vision testing at that later point, a smaller and not necessarily identical group, the reported average gain was 29 letters, nearly six lines, bringing vision to roughly 20/120. Seventy-eight percent of those patients, 14 of 18, had improved by at least 15 letters, or three lines, a threshold researchers consider clinically meaningful. The 36-month figures come from a conference presentation rather than a peer-reviewed publication, so they should be read as encouraging early evidence of durability rather than a final, confirmed picture of long-term outcomes for everyone who receives the implant.

    Chart showing ETDRS vision line gains at year 1 and year 3, and share of patients with meaningful improvement
    Average vision gains grew slightly between year 1 and year 3, and 78% of evaluable patients reached a clinically meaningful improvement.
    “In clinical trials, PRIMA is working better at month 36 than it did at month six.” — Max Hodak, co-founder and CEO of Science Corporation

    Two further findings add context. With the implant switched off, so that patients were relying only on whatever natural vision remained, that baseline vision stayed essentially unchanged over three years, a reassuring sign even though it does not, by itself, rule out subtler structural effects on the retina. Meanwhile, patients’ untreated fellow eyes kept losing vision, as geographic atrophy typically does without any intervention. On safety, researchers reported no new type of safety signal between 12 and 36 months; in the original 12-month study, serious adverse events were concentrated in the weeks after surgery and mostly resolved within two months, though a smaller follow-up group makes it harder to rule out rare or delayed complications.

    Recovering Some Ability to Read

    Geographic atrophy affects more than five million people worldwide and is among the leading causes of severe central vision loss in older adults, though many patients retain some peripheral vision. Approved treatments for the condition can only slow its progression; none had previously been shown to restore central vision that was already lost. That is what makes the PRIMAvera results notable: in the original 12-month study, 27 of 32 assessed participants were able to read letters, numbers or words using the implant, the clearest and best-documented functional outcome. Reports of patients managing longer passages or recognizing faces come from investigators and company accounts rather than a single standardized test, so they are best read as illustrative rather than guaranteed results for every patient.

    Researchers are careful to note that the device does not restore natural eyesight. Patients rely on it only in the implanted eye, need weeks of rehabilitation to learn to interpret its artificial signal, and see a simplified, lower-resolution image rather than full natural detail. Still, for people who previously had no reliable way to read, the functional gain is meaningful, which is part of why Dr. Frank Holz, the lead author of the original NEJM paper, has described the implant as “a paradigm shift in treating late-stage AMD.”

    How the PRIMA Chip Restores Sight

    PRIMA is a wireless chip measuring 2 by 2 millimeters and just 30 microns thick, about half the thickness of a human hair, surgically placed beneath the retina in the area damaged by geographic atrophy. Patients wear glasses fitted with a miniature camera that captures the scene in front of them and projects it onto the chip as pulses of near-infrared light, invisible to the eye, rather than ordinary visible light. A built-in zoom feature lets patients magnify text.

    The chip’s surface works like a miniature solar panel, covered with microscopic photovoltaic pixels that convert the infrared light into small electrical currents. Those currents stimulate the retinal neurons that normally relay visual signals toward the brain, in the same location where vision would ordinarily be processed if the light-sensing photoreceptor cells had not died. The brain then interprets the resulting pattern as a crude, pixelated image.

    The technology was originally developed by Professor Daniel Palanker at Stanford University and is now manufactured by Science Corporation, a neural-engineering company based in Alameda, California. PRIMA received the CE Mark in 2026, clearing it for sale, and the company says it is now commercially available in Europe and the United Kingdom, though in practice access will depend on which hospitals offer the surgery and on local funding arrangements. In the United States, PRIMA remains investigational and has not been approved by the Food and Drug Administration, though Science Corporation says an approval process is underway.

    Why Durability Matters So Much

    For implanted neurotechnology, the central question is rarely whether a device works at first, but whether the benefit lasts. Scar tissue can build up around an implant, electronics can degrade, and the body’s response to a foreign object can gradually blunt a signal that worked well in the first few months. Earlier generations of retinal implants, and some other neural devices, have shown promising short-term results that faded within a few years.

    That is why the 36-month PRIMAvera data matter more than a typical one-year readout. In a disease that normally only gets worse, average vision in the implanted eye did not just hold steady between 12 and 36 months; it continued to improve. “Three years after implantation, the patients who gained vision have kept it, even improved it,” said Dr. Mahi Muqit of Moorfields Eye Hospital and University College London, who presented the data. Researchers attribute part of the extra gain to patients becoming more skilled at interpreting the implant’s artificial signal with practice, and part to evidence that the hardware itself remains stable in the eye over time.

    Who Can Access It, and Who Can’t

    For now, PRIMA is commercially available only in Europe and the United Kingdom, and only for geographic atrophy caused by age-related macular degeneration; it has not been tested as a treatment for other causes of vision loss, such as inherited retinal disease or diabetic eye disease. Even where it is approved, access will likely stay limited at first to specialized retinal surgery centers, given the operation required to place the chip and the weeks of visual rehabilitation that follow.

    In the United States, the device remains investigational, meaning patients can currently obtain it only by enrolling in a clinical trial, if one is available, while the FDA approval process continues. An editorial accompanying the original one-year results in The New England Journal of Medicine described PRIMA as the first approach shown to restore vision, rather than merely slow its loss, in advanced geographic atrophy, a framing that underscores how little direct competition this approach has today, and how much is still being learned about its place in everyday eye care.

    Caveats Behind the Headline Numbers

    The study design leaves real uncertainty. PRIMAvera had no control group, so researchers cannot fully separate the implant’s own effect from a practice effect, in which patients simply get better at using the device’s artificial signal over time regardless of how the hardware is performing. Larger, controlled trials would be needed to settle how much of the measured improvement comes from the chip itself.

    The shrinking sample size is also worth noting: of the 38 people originally implanted, only 27 remained evaluable for safety and 18 for vision at the three-year mark, and the publicly presented data do not explain why the others dropped out of assessment. If patients who were doing poorly were more likely to leave the study, the remaining group could make the device look more effective than it actually is across everyone who receives it.

    Whether PRIMA reaches more patients in the United States, and how it performs in a larger and more varied population, remains to be seen. But for a disease that has long offered people only the prospect of a slower decline, three years of durable, measurable improvement is a meaningful data point, and one that eye specialists are likely to watch closely as the device moves toward wider use.

    Sources: Science Corporation, Newswise / American Academy of Ophthalmology

  • [Science] A ‘DNA Typewriter’ Maps How One Cell Becomes a Mouse — Clues to Birth Defects, Cancer

    [Science] A ‘DNA Typewriter’ Maps How One Cell Becomes a Mouse — Clues to Birth Defects, Cancer

    Every mammal begins life as a single fertilized egg. Through repeated divisions and a long sequence of developmental decisions, that one cell gives rise to the many specialized cells that build an animal’s body. Reconstructing exactly how those cells are related to one another has been a major scientific challenge — researchers have never had a detailed, verified map of which cell gave rise to which inside a living mammal. Two research teams have now taken a significant step toward solving that problem, publishing independently in the same week. Using DNA-based molecular recorders built into mouse embryos, they worked backward from genetic marks left behind in cells to reconstruct how a single fertilized egg becomes a full body. The work could eventually help researchers investigate how birth defects, neurodevelopmental conditions, and cancer arise.

    A Lineage Record Written Into DNA

    The core tool, called DNA Typewriter, was developed by a University of Washington (UW) School of Medicine team that includes geneticist Jay Shendure and researcher Junhong Choi. It is built on prime editing, a precise form of CRISPR-based gene editing that rewrites short stretches of DNA without fully cutting both strands. The team engineered a short, designated sequence into cells’ genomes and set it up so that each cell division adds one new mark, in strict order, to that sequence. Because the marks accumulate like letters typed one after another, researchers can later read the resulting sequence in any surviving cell and reconstruct which cells share a recent common ancestor and which branched apart earlier — in effect, rebuilding a family tree after the fact, rather than filming it as it happens.

    Older lineage-tracing systems generally relied on CRISPR methods that cut DNA to create heritable barcodes. Those barcodes can be powerful, but as edits pile up they can become harder to read unambiguously, and some lineage information is inevitably lost along the way. Because DNA Typewriter writes new sequence without the same kind of DNA break, the team reports it can keep recording more steadily, at higher resolution, for longer than earlier cut-based approaches — though, like any method, its performance still depends on how efficiently it operates inside developing cells.

    One Richly Recorded Embryo

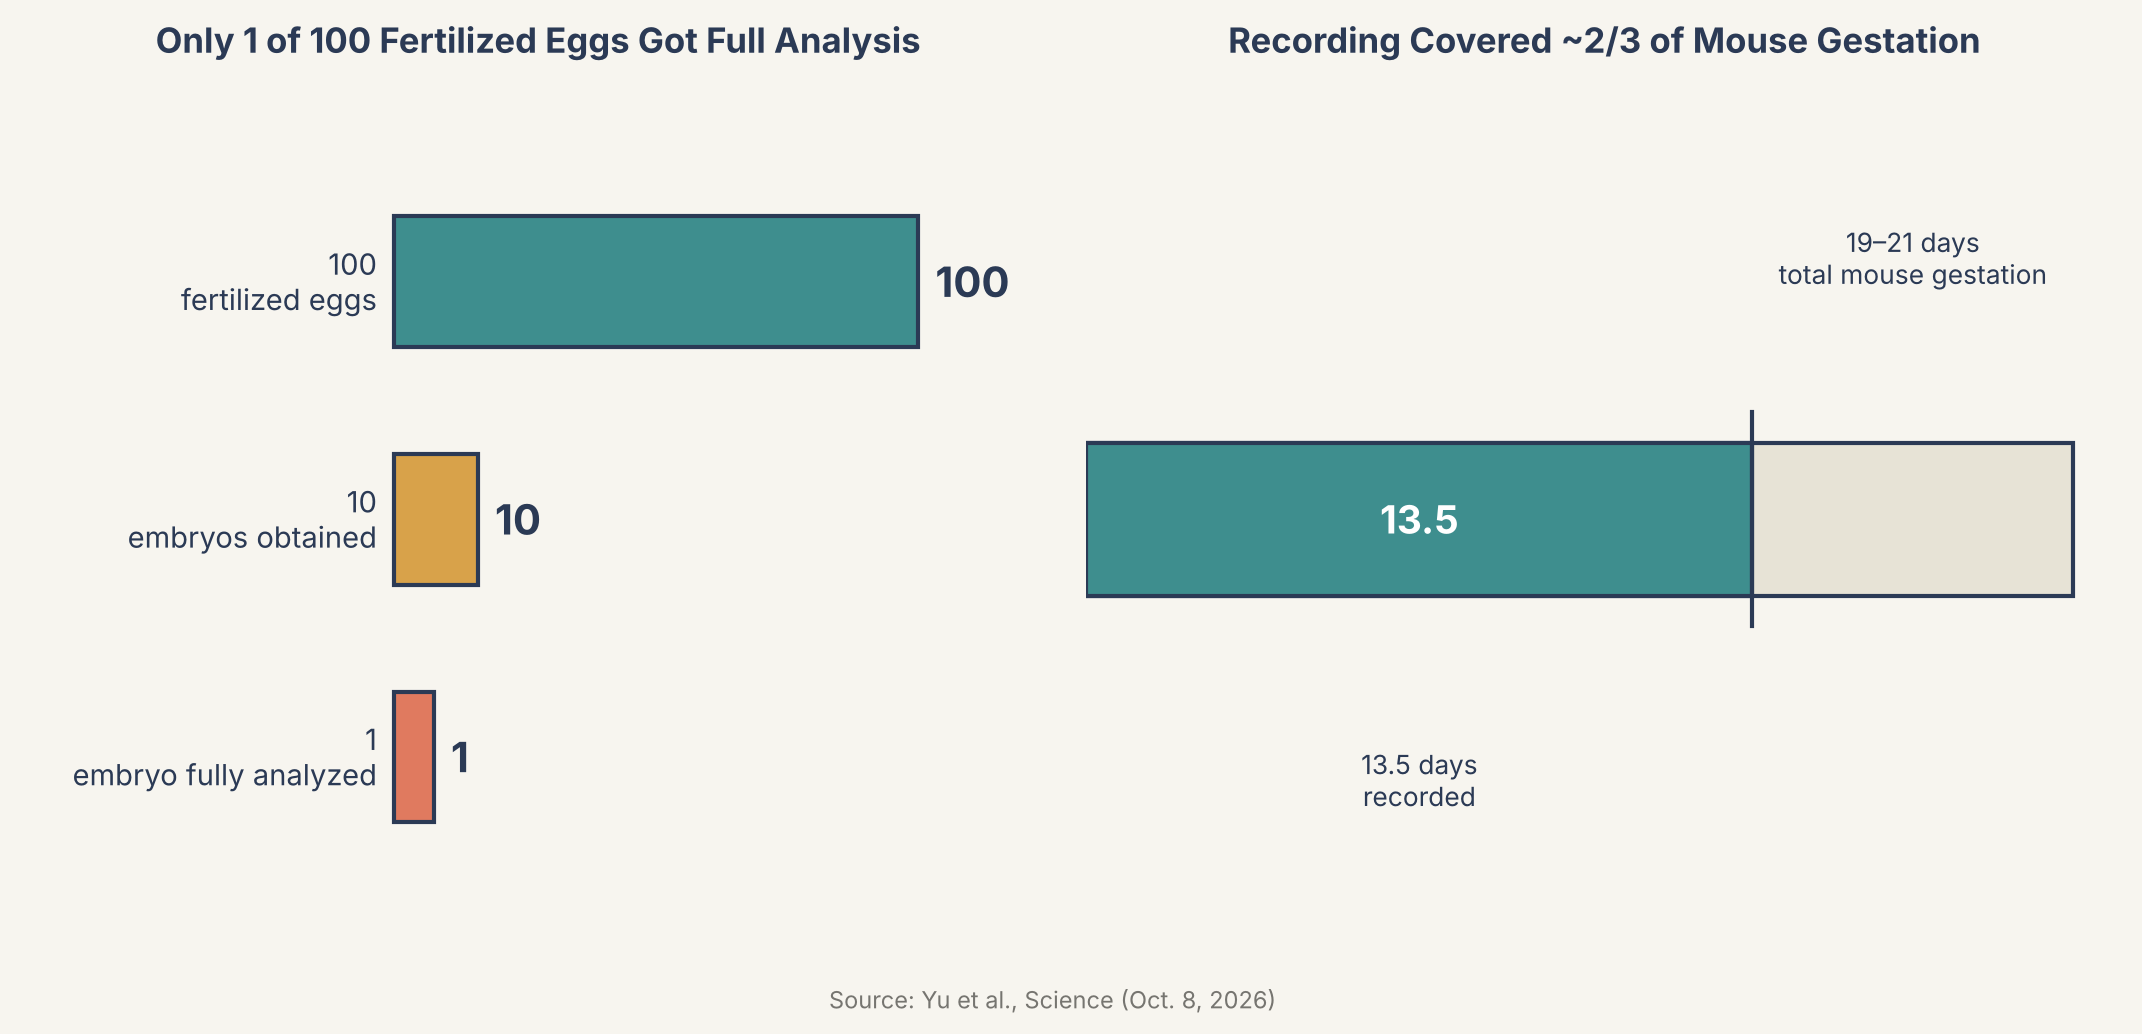
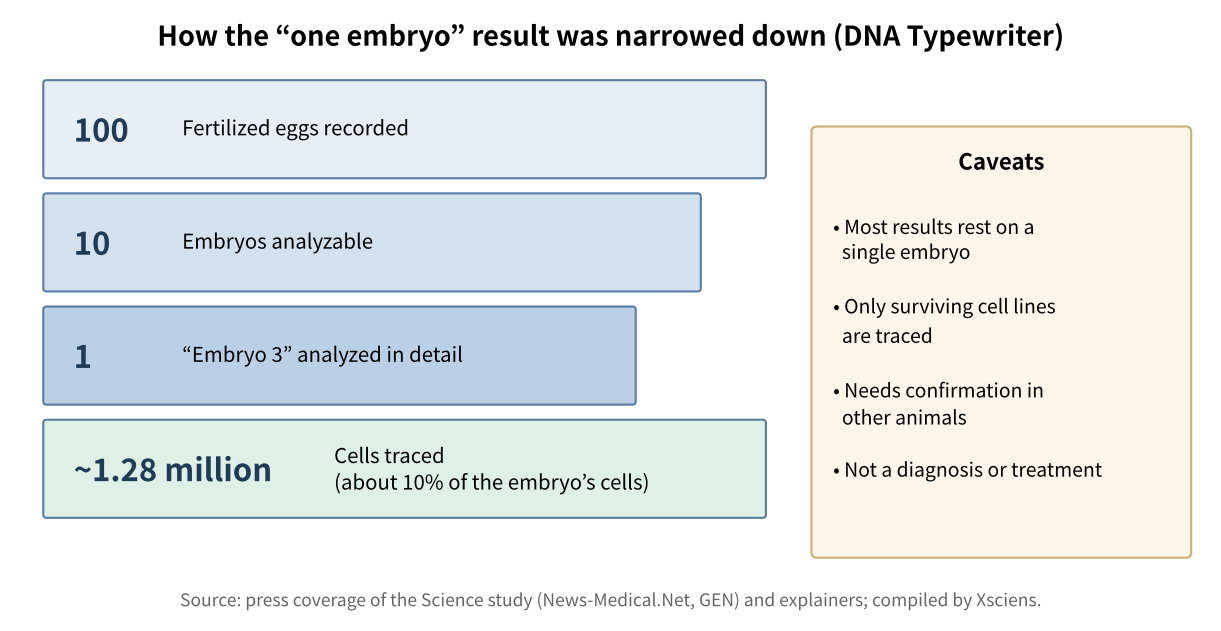
    In the new study, published October 8, 2026 in the journal Science, the UW-led team — including co-first authors Qi Yu, Haedong Kim and Sophie Seidel, with Chengxiang Qiu of Dartmouth College and Shendure as co-senior authors — attempted to activate DNA Typewriter recording in 100 fertilized mouse eggs. Only 10 developed into embryos that could later be examined, and of those, one — labeled Embryo No. 3 — carried by far the richest, most complete record. That embryo became the basis for the study’s detailed lineage reconstruction, which covered roughly 1.3 million individual embryonic cells.

    The recording spanned 13.5 days of development, from the fertilized egg’s first division through “late organogenesis,” the stage when the body plan and internal organs have largely taken shape. A full mouse pregnancy lasts 19 to 21 days, so the reconstruction covers a large share of gestation, though not the full life cycle. As co-first author Haedong Kim put it, the goal was a tool that “writes everything in strict order so that we can record cell lineages at much higher resolution for a longer time” than earlier barcoding methods allowed.

    Chart showing 100 fertilized eggs yielding 10 embryos and 1 fully analyzed, and 13.5 of 19-21 days of mouse gestation recorded
    Source: based on data from Yu et al., Science (Oct. 8, 2026)

    Two Founder Cells, One Shared Outcome

    A built-in mark distinguished the two cells created when the fertilized egg first divided, letting researchers trace nearly every profiled cell in the embryo back to one of those two founders. One founder went on to produce noticeably more descendant cells than the other. Yet both founders generated a broadly similar mix of cell types in roughly equal proportions — meaning that an early imbalance in how many cells each founder produced did not translate into one founder specializing in different tissue types than the other.

    The data also pointed to differences in timing: some blood and retinal cell populations showed signs of settling into a restricted identity relatively early in development, while cells contributing to the outer layer of skin appeared to keep their options open for longer. That kind of timing information — not just which cells are related, but roughly when their developmental paths narrowed — is difficult to extract from a single still snapshot of tissue, which is part of why a continuous lineage record is valuable.

    A Second, Larger-Scale Study Agrees

    The same week, a separate team led by Jonathan Weissman published a companion study in the journal Cell, using a related but distinct prime-editing-based system called PEtracer. Rather than following a single embryo in exhaustive detail, that study pooled data from 16 mouse embryos spanning days 7.5 to 10 of development, profiling more than 1.4 million cells in total to build a broader, population-level map of when and how cells commit to their fates. The two approaches are complementary: DNA Typewriter trades breadth for an unusually dense, ordered timeline in a single animal, while PEtracer trades timeline detail for scale across many animals. That two independently developed methods, from different labs, point toward a broadly consistent picture of mouse development adds useful weight to both — without, of course, each study individually confirming every specific claim made by the other.

    “This kind of large-scale developmental recording gives scientists a map of how one cell becomes a whole body,” says Haedong Kim, co-first author of the Science study.

    Weissman has framed the pair of studies as a long-sought proof of principle: that mammalian biology may finally be approaching something like the complete cell lineage map that biologist John Sulston built for the roundworm C. elegans back in 1983, by directly watching the worm’s roughly 1,000 cells divide under a microscope over years of painstaking observation. A mouse — and, by extension, a human — is built from many billions of cells, far beyond what direct visual tracking could ever handle. Genomic recording tools like DNA Typewriter and PEtracer offer a different route toward that same kind of detailed lineage map, built from molecular records and computational reconstruction rather than a person watching through a lens.

    Funnel from 100 fertilized eggs to 10 analyzable embryos, 1 detailed embryo and about 1.28 million traced cells, with caveats
    How the experiment was narrowed down, and how to read the result (compiled by Xsciens from press coverage and explainers).

    Why This Matters for Medicine

    The appeal of this kind of lineage map goes beyond curiosity about development for its own sake. If researchers can see roughly how and when healthy cells commit to becoming blood, skin, or retina, they gain a reference point for recognizing what might go differently in congenital malformations, in neurodevelopmental conditions linked to early brain development, and in genetic diseases more broadly — as a way to investigate how developmental abnormalities arise, not as a diagnosis or treatment in itself. Cancer researchers are watching this space too, since tumors can, in part, involve cells that lose normal control over their fate decisions, among other changes; fine-grained lineage data is one more tool for studying how abnormal cell populations evolve over time. Xsciens has previously reported on research into how an existing cancer drug affects brain tumor cells, a reminder that untangling cellular mechanisms in detail, lineage included, is an active front across cancer research generally. Longer term, scientists studying stem cells hope lineage maps like these could help guide how lab-grown cells are coaxed into becoming the right tissue for future cell-based therapies.

    It’s worth being clear about the limits here. The DNA Typewriter study’s richest results come from a single mouse embryo out of ten examined; broader validation across more animals, and eventually work beyond mice, will be needed before the tool becomes a routine research platform. Both systems have so far only been used in laboratory mouse embryos, not in humans, and translating developmental insights from mice to people remains its own multi-step scientific challenge. Even so, having two independent, broadly converging demonstrations published within the same week is a meaningful sign that genomic cell-lineage recording has moved from a promising idea toward a working research tool — one whose maps are highly informative, even if not yet complete.

    Xsciens Editorial Note

    “DNA wrote down how one egg becomes a body” is an appealing story, but it helps to weigh the numbers first.

    • What was shown. A method that writes marks into DNA without cutting it traced a “family tree” of about 1.28 million cells over 13.5 days. A separate team’s method reported similar results, so the direction has some support.
    • What is still open. The detailed analysis rests on one embryo out of 100 eggs, and the traced cells are about 10% of the embryo. Coverage of the study notes that dead cells leave no record and that confirmation in other individuals is needed.
    • A caution when reading. “Clues to birth defects and cancer” in the headline is about future uses. The study itself did not demonstrate any diagnosis or treatment.
    • Our imagination (speculation) — We wonder whether, as this family tree grows, disease researchers might be able to compare against a kind of standard map of “where does this cell come from when everything is normal?” That could make it easier to discuss at which branching step a congenital condition arises. But until the method works reliably across many individuals, that remains a long way off, and this is our speculation.

    References for this note: The Brighter Side, “Scientists construct a ‘family tree’ containing 1.28 million cells from a single embryo” (figures from the Science study and the limitations it lists)

    Sources: News-Medical.Net, Genetic Engineering & Biotechnology News (GEN)

  • AI Summaries Can Distort Human Memory — A Warning for Police and Witnesses

    AI Summaries Can Distort Human Memory — A Warning for Police and Witnesses

    You watch a short video of a car approaching an intersection, notice the traffic sign, and see it strike a pedestrian. The next day, you read an AI-generated summary of that video, one that happens to get the sign wrong. Asked afterward what you actually saw, you become measurably less likely to answer correctly. That is the core result of a new study from Georgetown University and the University of Washington: a misleading AI summary can distort people’s memory of an event they witnessed directly, which matters because AI-generated summaries are already spreading into newsrooms, offices, and policing.

    Illustration: video summarized by AI, with details breaking off before reaching memory
    From video to AI summary to memory: small details can break off and go missing along the way — an illustration of the distortion effect described in this article.

    AI Summaries Are Already Everywhere

    Large language models like ChatGPT and Gemini are now routinely used to condense meeting recordings, news footage, and surveillance video into a few bullet points. Some U.S. police departments have gone further, adopting separate tools that draft incident-report narratives from transcribed body-camera audio. One such product, Axon’s Draft One, generates a draft within minutes of a call ending, which an officer must then review and approve; the Fort Collins, Colorado police department has reported an 82% drop in time spent writing reports after adopting it. That tool drafts text from audio transcripts rather than summarizing video, and it was not tested in this study — but it illustrates how quickly AI-written accounts are entering settings where accuracy carries real stakes.

    That broader shift is what worries the study’s authors. “AI is a new method of delivering misinformation,” said lead author Mattea Sim, an assistant research professor at Georgetown’s McCourt School of Public Policy. Co-author Yael Eiger, a Ph.D. candidate at the University of Washington who studies technology in policing, put it more bluntly: she said it concerns her that police departments may already be relying on video-summarization technology without the kind of testing this study attempted.

    Testing Memory With a Car-Crash Video

    The researchers ran their test in two stages. First, they asked ChatGPT-5.5 and Gemini 2.5 Flash-Lite to summarize two short animated videos of a car-pedestrian collision. The two videos were nearly identical except for one detail: one showed the car approaching a stop sign, the other a yield sign. Each model summarized each video five times, producing 20 summaries in total.

    Second, 360 people were recruited to watch one of the two videos themselves. One to two days later, the researchers had each participant read a summary of what they had just seen — either an accurate one or one with a single planted error that reversed the key sign detail — and told them, at random, that the summary had been written by either an AI system or a human transcriber. Of the 360 who started, 328 completed both stages and passed an attention check.

    Most Summaries Omitted the Key Event

    Before testing human memory, the researchers first graded the 20 AI-written summaries against a list of details the researchers had identified as central to the event. The results were not reassuring: on average, the summaries omitted 51.6% of those central details, and 19 of the 20 summaries failed to mention the single most important one — the car hitting the pedestrian.

    The two models differed in other ways. Every summary from both ChatGPT and Gemini contained at least one error. Gemini’s summaries included a critical inaccuracy — one that reversed a core fact, such as the traffic sign, rather than just dropping a minor detail — in all of its summaries, compared with 30% for ChatGPT. Both models also occasionally invented details that were never in the video at all, a pattern researchers call hallucination. These figures come from a small, controlled test of two models summarizing two short videos, so they should be read as evidence that serious errors can occur rather than as a general failure rate for AI video summaries.

    “AI has the potential to generate misinformation, even absent any adversarial intent,” the study authors write.

    A Wrong Summary Cut Recall Nearly in Half

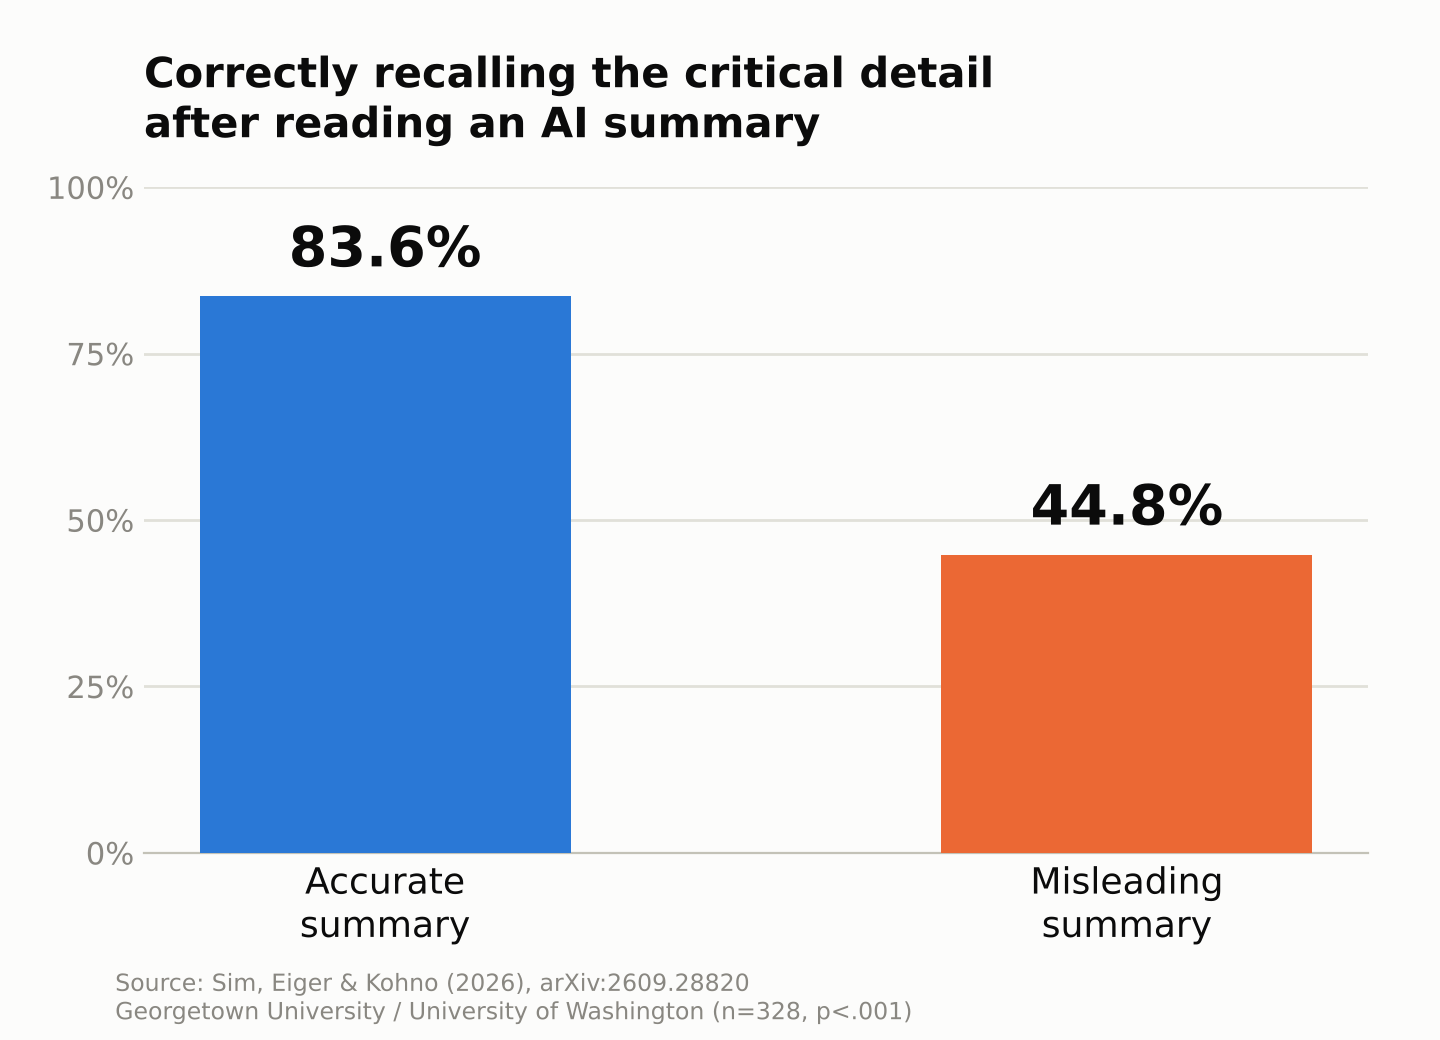
    The second stage showed these errors don’t stay confined to the summary — they appear to bleed into people’s own memory of the event. Participants who read an accurate summary correctly identified the sign 83.6% of the time. Among those who read the summary with the planted error, accuracy dropped to 44.8%, a gap the researchers found to be statistically significant and unlikely to be explained by chance alone.

    Bar chart comparing recall accuracy

    That 38.8-percentage-point gap is the study’s central finding: a single misleading detail, embedded in an otherwise ordinary-looking summary, substantially reduced participants’ ability to correctly recall a detail they had directly observed just one or two days earlier. The experiment shows a clear misinformation effect; it doesn’t by itself prove that the original memory was erased or permanently replaced, only that recall of this one detail became much less reliable.

    Source Labels Alone Didn’t Help

    One of the more striking results is what didn’t matter. Participants told the summary came from an AI were no more accurate, and no less likely to be misled, than those told a human wrote it: 46.3% versus 43.4%, a difference too small to be statistically meaningful. How much participants said they trusted AI in general, or how often they used it, also made no measurable difference.

    In this experiment, simply labeling a summary as AI-generated rather than human-written did not reduce the misleading effect. The researchers say this challenges a common assumption in AI-safety discussions — that keeping a “human in the loop,” meaning a person who reviews the AI’s output, is enough to catch its mistakes. If a misleading summary quietly shapes the reviewer’s own recollection of the source material, that reviewer may be less able to notice anything is wrong. The study did not test other safeguards, such as requiring reviewers to check specific claims against the original recording, so it can’t yet say which interventions would actually help.

    Why This Matters for Courts and Policing

    The experiment used an animated video, student volunteers, and a lab setting — not real police officers, real witnesses, or an actual criminal case. Its relevance to policing is more general: when an AI-generated account becomes part of how someone reconstructs what happened, errors in that account may shape what they later remember. If an officer or witness reads an inaccurate AI-generated recap of body-camera footage before giving a formal statement, that recap could influence their later recollection — a real concern, though not one this particular study tested directly.

    This isn’t only a human blind spot, either. A separate study covered previously on this site found that AI vision systems fail to reproduce the same motion illusions that trick the human eye — one more reminder that machine and human perception can diverge in either direction, so neither can simply be trusted to check the other without independent verification (see our earlier coverage of AI vision and motion illusions).

    A condensed version of this research was presented this week at the Ninth AAAI/ACM Conference on AI, Ethics, and Society (AIES 2026), held October 12–14 in Malmö, Sweden, after first appearing as a preprint in September. The authors aren’t calling for AI summaries to be banned from sensitive uses, but they argue error rates like these need to be measured and disclosed before such tools are trusted with decisions that affect legal outcomes.

    The researchers are also upfront about what they didn’t test. They used only consumer-facing versions of ChatGPT and Gemini, not the enterprise or custom-tuned models that vendors like Axon actually deploy, and the AI error-rate analysis covered just two short animated videos. Eiger says that gap is itself part of the problem: outside researchers generally have little visibility into which exact models or settings police vendors use, which makes independent auditing difficult. Sim says a natural next step is to study real body-camera footage and real police reports directly, to see whether AI-generated summaries measurably shift how people judge a police-civilian interaction — not just a simple traffic-sign detail in an animated clip.

    Xsciens Editorial Note

    The finding is not simply that “AI makes mistakes”; it is that a single wrong detail can slip into a person’s memory and quietly bend the judgment of the human who is supposed to be checking.

    • Read the 38.8-point gap in context. Accuracy was 83.6% after an accurate summary and 44.8% after a misleading one. But this comes from two short animated videos, two AI models, and 328 analyzed participants, so it is not an error rate for AI summaries in general.
    • An “AI-written” label did not help. Accuracy was 46.3% when people were told an AI wrote the summary and 43.4% when told a human did, with no meaningful difference. The study did not test checking steps such as comparing against the original video, so it does not show that human review is useless, only that review has to be designed carefully.
    • Not a test of real police tools. The participants were volunteers watching animations, not officers or witnesses in real cases. The classic Loftus and Palmer experiments had already shown that the wording of a question can change what people remember, so the new element here is the AI-generated text as the source of the distortion.
    • Our imagination (speculation) — We wonder whether future AI summaries that show the exact moment of the video each sentence is based on, so you can jump to it in one click, might make errors easier to catch. A meeting recording that lets you tap a line and hear the original remark is one example. But if people skip the check even when the evidence is one tap away, the same problem could remain, so this is only our speculation.

    References for this note: Georgetown University press release, the paper (arXiv:2609.28820), Loftus & Palmer (1974), explained (SimplyPsychology)

    Sources: Georgetown University, “New Research Finds That Misleading AI-Generated Summaries Can Distort Human Memory”, Sim, Eiger & Kohno, “AI-Enabled Human Memory Manipulation” (arXiv:2609.28820), Axon, “Axon Reimagines Report Writing With Draft One” (via Officer.com)

    See also: our explainer on cognitive offloading, the habit of handing memory and thinking to tools.

  • [Science] A Sulfur Crystal Turns Sunlight Into Hydrogen — A Step Toward Cheaper Fuel

    [Science] A Sulfur Crystal Turns Sunlight Into Hydrogen — A Step Toward Cheaper Fuel

    Chemists at Oregon State University have built a new crystalline material that uses sunlight to produce hydrogen from water, without bolting on a separate, expensive metal catalyst to make the reaction run. The work, published in the Journal of the American Chemical Society, does not come with a price tag or a factory timeline yet, but it offers a concrete lead on one of clean hydrogen’s biggest obstacles: catalysts that are too costly to use at the scale the energy system would need.

    Illustration of sunlight striking a crystal submerged in water, releasing hydrogen bubbles

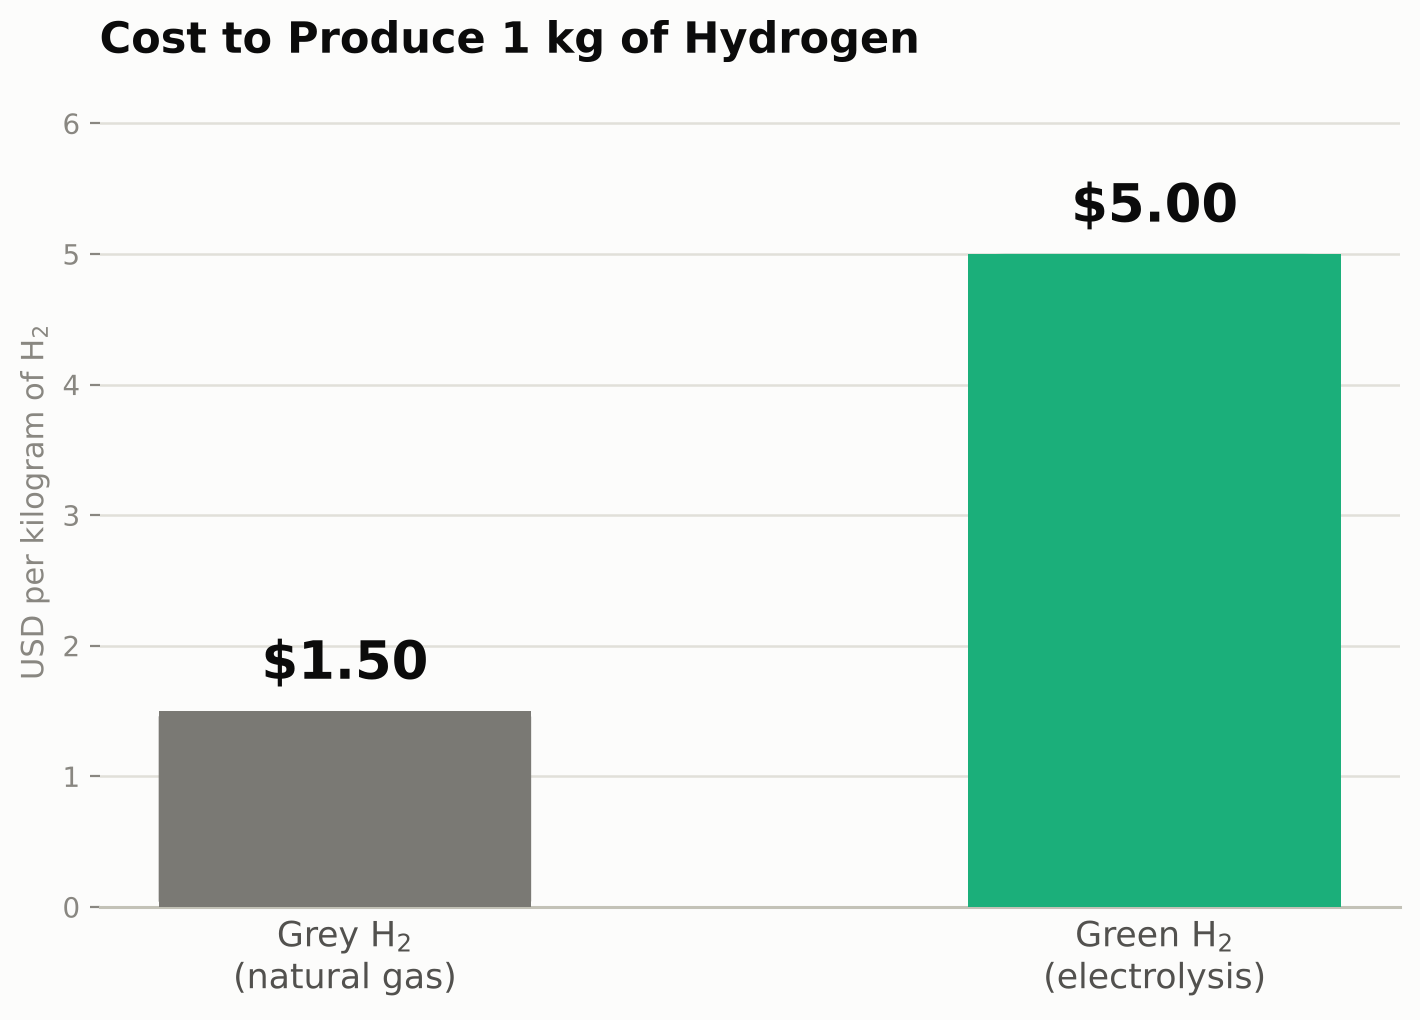
    Hydrogen is widely discussed as a fuel for ships, heavy trucks, steelmaking, and chemical plants that are hard to run on batteries alone, since it can generate electricity in a fuel cell with water as the main byproduct. The catch is how the hydrogen gets made. Today, hydrogen production is dominated by fossil fuels, mostly natural gas processed through a method called steam-methane reforming, with coal gasification also contributing a significant share, particularly in parts of Asia. That hydrogen is relatively cheap, on the order of $1.50 per kilogram by Oregon State’s figures, but it releases carbon dioxide in the process, which undercuts much of the climate case for switching to hydrogen in the first place.

    Hydrogen made by splitting water with renewable electricity or sunlight, often called green hydrogen, avoids that emissions problem, but it typically costs around $5 per kilogram today by the same estimate, more than three times as much. These are illustrative, broad figures rather than fixed prices; actual costs swing with local energy prices, plant scale, and technology. Still, part of the gap comes down to hardware: some electrolyzers and photocatalytic systems rely on precious-metal catalysts, platinum among them, to drive the reaction fast enough to be practical, and those materials are not cheap.

    Catching Light With Sulfur, Not Metal

    The Oregon State team, led by chemist Kyriakos Stylianou of the university’s Materials Discovery Laboratory, built a metal-organic framework, a class of crystalline, extremely porous materials assembled from metal ions linked together by organic molecules, that they call BVR-19. It forms spontaneously in water at room temperature, a synthesis route the researchers say avoids the high heat or pressure many materials need, though how that translates into a final production cost has not been established.

    The structural feature that matters most sits inside BVR-19’s organic linkers: a bond between two sulfur atoms that briefly breaks apart when struck by light, generating short-lived, highly reactive sulfur species. According to Oregon State’s announcement, it is these organic, sulfur-containing building blocks that help capture light energy and move electrons to where hydrogen is ultimately produced, working alongside the framework’s metal centers rather than leaving the metal to do that job alone.

    Cost comparison of grey and green hydrogen production, per kilogram in USD
    Source: approximate figures cited alongside Oregon State University’s announcement

    Metal-organic frameworks have drawn growing interest across chemistry over the past two decades because they are so tunable: change the metal, change the organic linker, and the pore size, surface area, and chemical behavior of the resulting crystal can shift dramatically, all within the same basic scaffold. That tunability is also what let the Oregon State team probe BVR-19’s inner workings, discussed next.

    Skipping the Bolted-On Metal Catalyst

    Photocatalytic water splitting conventionally needs more than a light-absorbing material: it usually also requires a separate metal co-catalyst, often platinum, physically attached to the structure to help the hydrogen-forming step run efficiently. Oregon State’s announcement describes BVR-19 as needing no additional expensive metal catalyst for that job, since its organic sulfur chemistry already contributes much of the light capture and electron transfer that a bolted-on catalyst would otherwise be doing.

    That should not be read as “metal-free.” BVR-19 still contains a metal center as part of its crystalline framework, and the team found that changing which metal sits there measurably changed how well the material performed, meaning the metal is far from irrelevant to the chemistry. The real, narrower claim is that no extra, separately added metal catalyst has to be layered on top of the base material the way platinum often is in other systems. It is a distinction worth keeping straight, because the innovation here is removing an added manufacturing step and its cost, not removing metal chemistry from the picture entirely.

    From One Experiment to Design Rules

    To understand why some versions of the framework outperformed others, the team systematically swapped out the metal ion at BVR-19’s core while leaving the rest of the structure essentially unchanged, then compared how each version performed under light. That side-by-side comparison let them connect differences in hydrogen output to specific changes in the material’s electronic structure, giving them a mechanistic explanation for why certain versions work better rather than only an empirical ranking of which ones do.

    “Our work provides a blueprint for designing better materials that can bring down the cost of green hydrogen,” Stylianou said in the university’s announcement of the findings. The team frames the result as a design principle to test and build on in future materials, rather than a finished, optimized catalyst.

    Research groups elsewhere are taking a similar mechanism-first approach to other energy-relevant reactions. A Kyoto University-led team, for instance, recently worked out in detail why a molybdenum molecular catalyst can convert nitrogen from the air into ammonia under comparatively mild laboratory conditions. In both cases, the advance was not a brand-new chemical but a clearer picture of why an existing catalyst behaves the way it does, which is usually what lets chemists improve a material on purpose instead of by trial and error.

    What Cheaper Hydrogen Could Unlock

    None of this means cheap, catalyst-light green hydrogen is imminent. Oregon State’s announcement and the peer-reviewed paper describe a laboratory-scale material and a design principle, not a measured hydrogen production rate, an efficiency figure, or a path to manufacturing; those numbers were not disclosed publicly alongside the findings. The work has not been tested at anything resembling industrial scale, and getting from a promising crystal in a lab to a working photocatalytic reactor typically requires years of further development, stability testing, and engineering, assuming it clears each step at all.

    What the study adds is a mechanistic foothold: evidence that letting an organic, sulfur-based structure share the light-absorbing and electron-transfer work can reduce a material’s dependence on costly bolted-on metal catalysts, at least in this framework, plus a method for figuring out which structural tweaks help and which do not. Whether that translates into cheaper hydrogen depends on factors the current study does not address, including the material’s hydrogen production rate, its durability over repeated use, and the cost of the reactor system built around it. If those later steps go well, incremental advances like this one, chipping away at the cost of individual components rather than reinventing hydrogen production overnight, are generally how energy technologies get cheaper over time. That is also what would let industries that are hard to electrify, such as steelmaking, shipping, and heavy trucking, lean more on low-carbon hydrogen instead of the fossil-derived hydrogen most of them use today.

    The project was funded by the Murdock Charitable Trust, the National Science Foundation, and Oregon State’s College of Science. For now, the result lives in a peer-reviewed paper and a university announcement, with the follow-up work, refining BVR-19, measuring its efficiency, and testing its durability, still ahead.

    Sources: Oregon State University, Journal of the American Chemical Society (DOI), ScienceDaily, Interesting Engineering

  • [Science] MIND Diet Linked to Years of Slower Brain Aging, 12-Year Study Finds

    [Science] MIND Diet Linked to Years of Slower Brain Aging, 12-Year Study Finds

    A diet designed around brain health may actually be protecting it. A 12-year study of nearly 1,650 American adults found that people who more closely followed the MIND diet — a hybrid of the Mediterranean and DASH diets — showed significantly slower shrinkage in brain regions tied to memory and thinking. Researchers calculate the effect as equivalent to roughly 2.5 years of delayed brain aging. The findings, published in the Journal of Neurology, Neurosurgery & Psychiatry, offer some of the strongest long-term evidence yet that everyday food choices in midlife may shape how the brain ages decades later.

    Inside the MIND Diet Study

    The MIND diet (Mediterranean-DASH Intervention for Neurodegenerative Delay) scores people from 0 to 15 based on how often they eat foods linked to brain health, such as leafy greens, berries, nuts, whole grains, fish, and olive oil, while subtracting points for red meat, fried food, sweets, cheese, and butter. For the new study, researchers from Zhejiang University, Harvard T.H. Chan School of Public Health, and the long-running Framingham Heart Study followed 1,647 adults from the Framingham Offspring Cohort, who were around 60 years old on average when the study began.

    Starting in the early 1990s, participants filled out detailed food-frequency questionnaires to calculate their MIND diet scores, with an average score of just under 7 out of 15 — meaning most people in the study were eating a moderately, not perfectly, brain-healthy diet. From 1999 onward, each participant underwent brain MRI scans roughly every few years — three scans on average — allowing researchers to track real changes in brain volume over a median follow-up of 12.3 years, rather than relying on a single snapshot. This repeated-measurement design is part of what makes the study notable: most diet-and-brain research relies on a single MRI scan compared against a single diet survey, which can only show a correlation at one point in time. Tracking the same people’s brains over more than a decade let the researchers instead measure the pace of change itself.

    Years of “Younger” Brain Structure

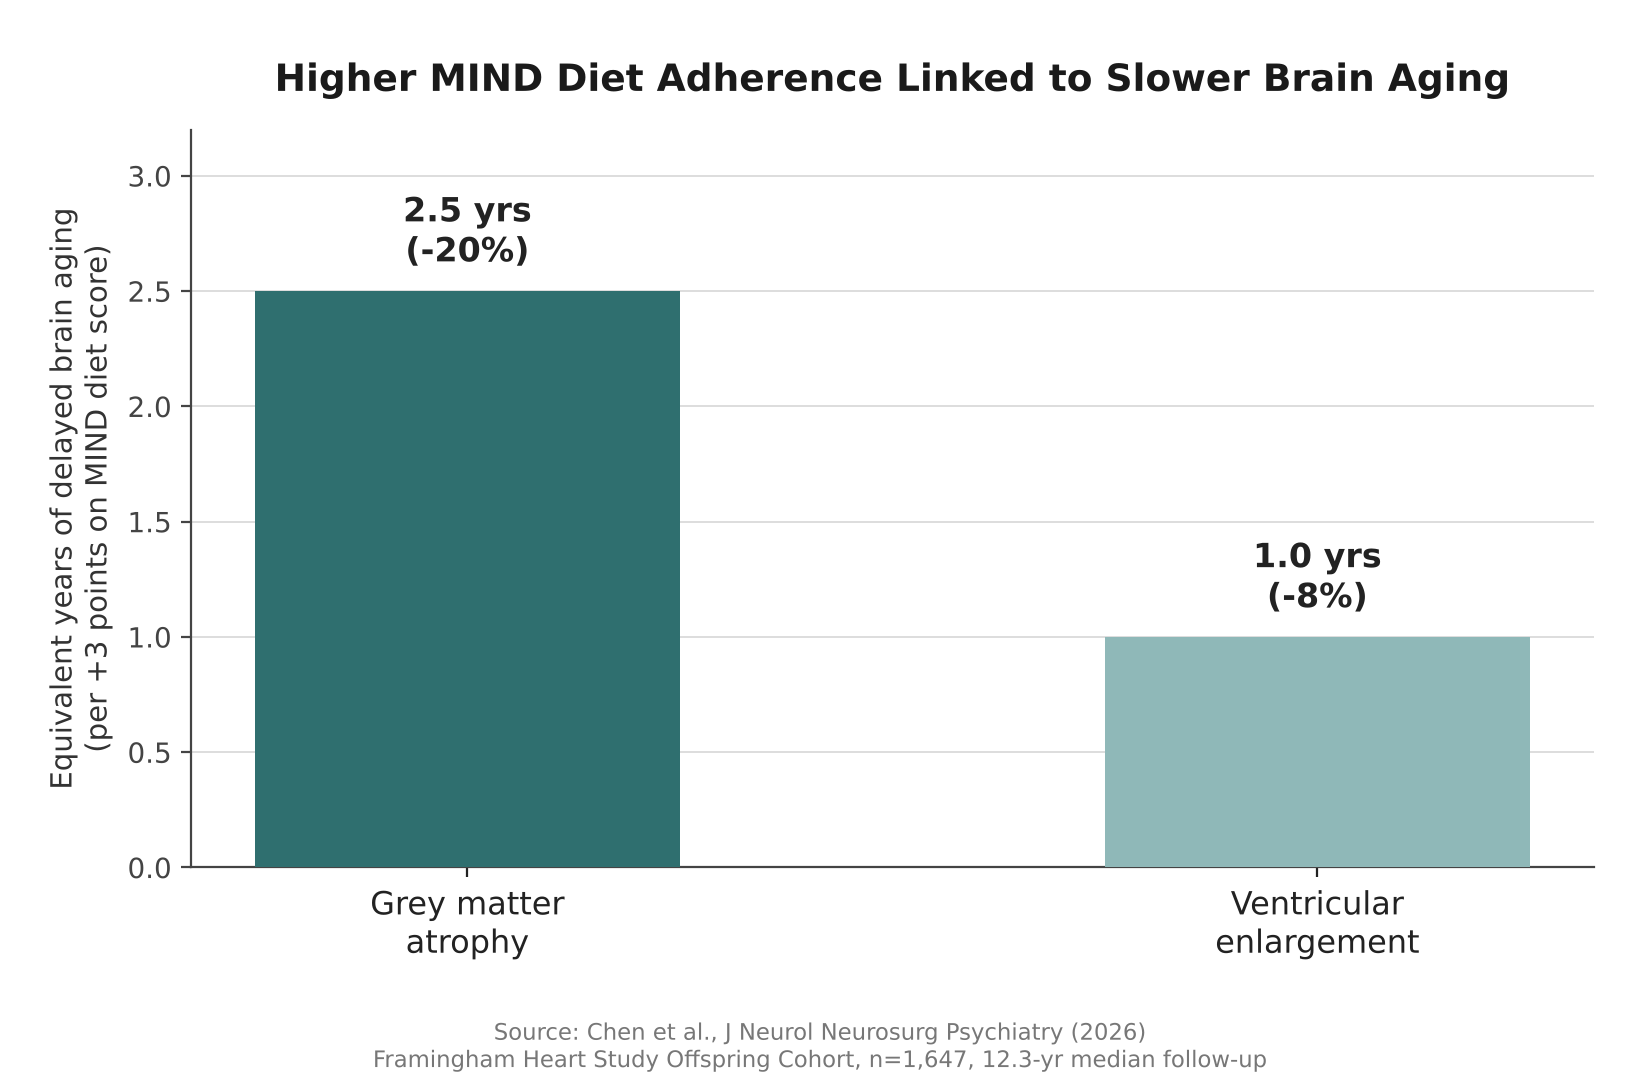
    The results were striking for an observational study. For every 3-point increase in MIND diet score, participants’ grey matter — the brain tissue that handles memory, decision-making, and sensory processing — shrank 0.279 cubic centimeters less per year, about 20% less age-related loss than would otherwise be expected. Researchers translated that gap into real-world terms: roughly 2.5 fewer years of brain aging.

    A 3-point higher MIND diet score was linked to about 2.5 fewer years of brain aging in grey matter volume — one of the clearest signals yet connecting everyday diet to long-term brain structure.

    Higher MIND scores were also linked to slower enlargement of the brain’s ventricles, fluid-filled spaces that expand as surrounding tissue is lost with age. That slower expansion — about 8% less than expected — translated to roughly one additional year of more youthful brain structure. Because all participants’ brains shrank somewhat over the study period, as is normal with aging, the real finding is about the pace of that decline, not whether it happened at all.

    Bar chart showing MIND diet score linked to years of delayed brain aging
    Source: Based on data from Chen et al., J Neurol Neurosurg Psychiatry (2026)

    Foods That Helped, and Surprised

    Not every food in the MIND diet scoring system behaved as expected once researchers looked food by food. Berries were linked to slower enlargement of the ventricles, and poultry was linked to both slower ventricular enlargement and slower grey matter loss — consistent with berries’ high antioxidant content and poultry’s role as a lean protein source, both of which may reduce oxidative stress that damages neurons over time.

    On the other end, sweets and fried fast food were linked to faster ventricular expansion and greater shrinkage of the hippocampus, the brain region most closely tied to memory formation. The researchers pointed to inflammation, unhealthy fats, and advanced glycation end-products — compounds that form when sugar reacts with proteins or fats in food, and which have been separately linked to tissue aging throughout the body — as possible mechanisms.

    Two results, however, ran against expectations. Whole grains, which earn positive points in the standard MIND scoring system, were associated with several unfavorable brain changes in this particular cohort, while cheese, which typically loses points, was linked to favorable ones. The study’s authors flagged both findings as unexpected and said they would need further research to explain, rather than drawing firm conclusions from them. One possibility researchers did not rule out is that people’s reasons for eating more or less of a given food — a doctor’s recommendation to cut dairy after a cardiovascular diagnosis, for instance — could confound a simple food-by-food analysis in ways a single study cannot fully untangle.

    Who Benefited Most

    The association between MIND diet adherence and slower brain aging was not uniform across the group. It was strongest among older participants, who face a faster baseline pace of brain aging and may have more to gain from protective factors. It was also stronger among people who were physically active and those who were not living with obesity, hinting that diet may work alongside — rather than instead of — other healthy habits.

    Participants who ate closer to the MIND pattern also tended to share other characteristics: they were more likely to be women and college-educated, and less likely to smoke or to have type 2 diabetes, high blood pressure, or cardiovascular disease. The researchers statistically accounted for these differences in their analysis, but they illustrate how diet quality tends to travel alongside a broader set of health behaviors.

    What This Study Can’t Prove

    Because this is an observational study, it cannot prove that the MIND diet alone causes slower brain aging. People who eat more healthily in general also tend to differ from others in exercise habits, education, and underlying health conditions, and some of the measured benefit may reflect those overlapping factors rather than diet in isolation. The food data also relied on questionnaires completed in the 1990s, which depend on participants’ memory and are vulnerable to reporting error, and the study could not fully rule out mild cognitive impairment at participants’ first brain scan or track how their diets may have changed over the following two decades.

    The study population was also overwhelmingly White, drawn from a single long-running cohort in Massachusetts, so it remains unclear how well the findings would generalize to more diverse populations. Still, the researchers conclude that their results “reinforce the potential of the MIND diet as a brain-healthy dietary pattern.” Diet is only one piece of the brain-aging puzzle — other recent work, including a study on how the Alzheimer’s risk gene APOE4 scars brain blood vessels, points to genetic and vascular factors working alongside everyday habits. Taken together, the evidence suggests that what people eat in midlife is worth taking seriously as a long-term investment in cognitive health, even before a formal clinical trial settles the question of cause and effect.

    Sources: BMJ Group, Journal of Neurology, Neurosurgery & Psychiatry (PMC)

  • [Economy] Engineers Who Skip the Patent System Are Leaving Pay and Credit on the Table: A Practical Guide

    Do you think of patents as “the IP department’s job” or “something for patent attorneys”? In reality, an engineer who doesn’t understand the patent system can end up missing out on compensation and career credit they’re legally entitled to — often without ever realizing it. The good news is that a few small habits are enough to turn your own technical work into fair compensation and a career asset. This guide covers the patent basics, then four things you can start practicing tomorrow, plus a daily checklist.

    0. The Patent Basics to Know First

    To be patentable, an invention generally needs three things: novelty (it doesn’t already exist in the world), an inventive step (a specialist in the field wouldn’t easily come up with it), and industrial applicability.

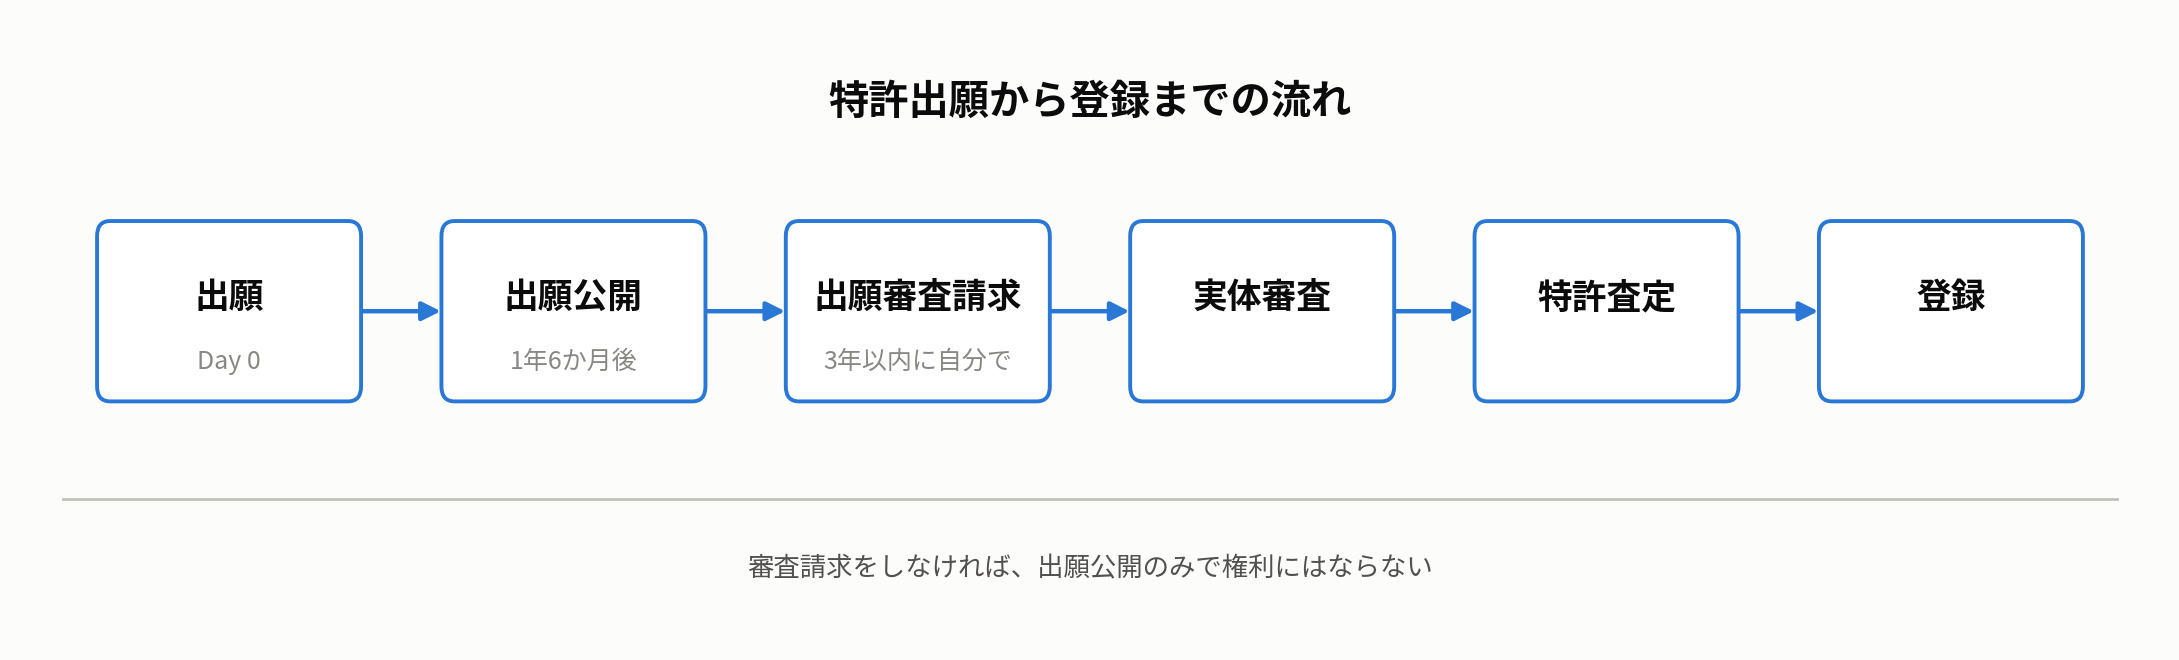
    The path from filing to a granted right runs: file the application → publication (automatically, 18 months after filing) → request for examination (you must request this yourself within 3 years of filing, or it’s never examined) → substantive examination → decision to grant → registration. If you never request examination, the invention’s contents simply become public — it never becomes an enforceable right.

    The single most important part of a patent is its “claims” — the scope of what’s legally protected. This is where the breadth and strength of the right is decided. No matter how detailed the written description is, any technology not captured in the claims isn’t protected.

    Diagram of the patent lifecycle: filing, publication, request for examination, substantive examination, decision to grant, registration
    The standard path from filing to registration. Note that examination never starts unless you request it yourself.

    1. Make Prior-Art Search Step One of Any New Project

    Running a patent search before starting a new project heads off two problems at once:

    • Reinventing the wheel: you avoid spending time building something that already exists, simply because you didn’t know about it.
    • Freedom-to-Operate (FTO) risk: discovering that a competitor already holds a patent on your approach, after the fact, can force a costly redesign or expose you to infringement risk.

    Japanese patent data can be searched for free, with no registration required, through J-PlatPat (the Japan Platform for Patent Information). As a beginner, three kinds of search will get you most of the way:

    • Keyword search — technical terms have multiple names, so connect synonyms with OR (e.g., “artificial intelligence OR AI OR machine learning”).
    • Applicant search — search by the name of a competitor or a related research institution to see which technologies they’re investing in.
    • FI/F-term (patent classification) search — use the classification codes the Japan Patent Office assigns to narrow down technical fields that keywords alone can’t capture.

    2. Read Patent Gazettes as a “Catalog of the Latest Technology”

    A patent gazette — especially the “published unexamined application” that comes out 18 months after filing — is a primary source packed with cutting-edge technical information that hasn’t made it into papers yet. You don’t need to read it cover to cover; reading in this order is efficient:

    • Abstract — grasp the gist of the invention in a few hundred characters.
    • Claims — check the scope the patent actually protects. Comparing this against your own design is the basis of an FTO check.
    • Description and drawings — for patents you’re genuinely interested in, dig into implementation details and examples.

    Even just tracking how filing volume in a given field is trending, or which companies are filing heavily on which technologies, tells you a lot about where the industry’s effort is going.

    3. Turn Ideas Into an “Invention Proposal” as Soon as They Come to You

    Even a great idea, if it’s only ever spoken aloud, leaves no record and never becomes a patent. Many companies follow an internal process like this:

    • The moment an idea occurs to you, jot down the date, the problem, the solution, and the effect — a notebook or an internal system is fine.
    • Propose it to your manager or IP staff using the company’s “invention proposal” format.
    • An internal invention review board judges whether it’s worth filing.
    • If it moves forward, you work with a patent attorney to build out the claims and description — and this is where it matters that the engineer conveys the technical content accurately.

    This is where Japan’s “employee invention system” (Article 35 of the Patent Act) comes in. Under the 2015 revision, if a company has specified in advance — through a contract or work rules — that it will acquire the right to obtain a patent, that right belongs to the company from the moment the invention is made. In exchange, the inventing employee is entitled to receive “reasonable benefit.” This isn’t limited to money — it can include other economic benefits under the company’s own programs, such as opportunities to study abroad or a promotion or award.

    Even when the right to a patent defaults to the company, Article 35 of Japan’s Patent Act guarantees the inventing employee “reasonable benefit” in return. Proposing an invention isn’t unpaid labor — it’s something the law entitles you to be compensated for.

    4. Turn Patents Into a Career Asset

    • Being named as an inventor is an objective credential that carries weight outside your company too. Patent gazettes list inventors by name, giving you concrete material to point to — “here’s what I created” — when changing jobs or during internal reviews.
    • Many companies run internal invention-recognition programs, rewarding inventions that contribute to commercialization with awards or bonuses.
    • The experience of writing a patent is also training in putting your own technology into words a third party can understand — a skill that raises the quality of your technical writing generally.

    A Practical Checklist

    • Before starting a new project, I’ve run at least one keyword search on J-PlatPat.
    • When an idea occurs to me, I jot down the date, the problem, and the solution on the spot.
    • I check the claims of competitors’ patents in technology close to our own products, and I’m aware of the infringement risk.
    • I know my company’s invention-proposal format and where to submit it.
    • I’ve at least once read through my company’s employee-invention rules (what counts as “reasonable benefit”).

    The essence of using patents well comes down to three unglamorous habits: record your ideas, search first, and read the claims. None of these require special skill — you can start today with nothing more than a notebook and a browser. Building patents into your own development process, rather than leaving them entirely to the IP department, looks like the long way around but is actually the shortest path.

    Japan Patent Office, “Overview of the Employee Invention System”
    Japan Patent Office, J-PlatPat (Patent Information Platform)

  • AI Vision Misses an Illusion the Brain Shows — A Gap Worth Testing

    AI Vision Misses an Illusion the Brain Shows — A Gap Worth Testing

    A new study finds that after watching something move, people briefly misjudge exactly where a now-still object is sitting — and a matching shift shows up in signals recorded from monkeys’ brains. The seven AI vision models the researchers tested, built to mimic human sight, did not reproduce that shift at all. Published October 2, 2026 in the journal Current Biology, the work from York University in Toronto does not prove that this gap causes real-world AI vision systems to fail. What it does offer is a precise, repeatable benchmark that engineers building self-driving cars, robots, and other systems that must track a changing scene could use to check whether their software handles recent visual history the way biological vision does.

    Static-image benchmarks, how often a system correctly names or locates an object in a single photo, have long been a mainstay of computer-vision research. But the study’s authors point out that real cameras rarely see the world as a single frozen frame; they see a stream of images shaped by whatever happened a moment earlier. Notably, even a video-based network in the test, built specifically to use multiple frames over time, did not reproduce the shift seen in biological vision. That suggests the gap is not simply about feeding AI more frames, but about a specific kind of recalibration that today’s architectures do not learn on their own.

    A Trick of Motion Fools the Brain

    The effect the researchers studied is related to the classic motion aftereffect, often called the waterfall illusion because it was first described by people who stared at flowing water. After watching motion in one direction — stripes sliding left, for example — a stationary object shown afterward can appear displaced in the opposite direction, even though its pixels have not moved at all. The York University team used this positional bias as a precise, measurable probe into how the brain represents where an object is, rather than treating it as a mere curiosity.

    Testing Monkeys, Humans, and Machines

    The research team, led by senior author Kohitij Kar and first author Elizaveta Yakubovskaya, ran related versions of the same basic test on three very different visual systems. Seventy-nine human volunteers, 35 in a no-motion baseline group and 22 in each of two adaptation-direction groups, briefly saw an object flash on screen for a tenth of a second and clicked where they thought it was. Two rhesus macaques viewed similar sequences while chronically implanted electrode arrays recorded signals from more than 150 neurons in the inferior temporal (IT) cortex, a region of the brain’s object-recognition pathway whose activity also happens to carry information about where an object sits. The same images were then fed into seven widely used computer-vision models, ranging from classic image classifiers such as AlexNet and VGG-16 to a vision transformer and a video-based action-recognition network called SlowFast.

    AI Could Find Objects, Not the Illusion

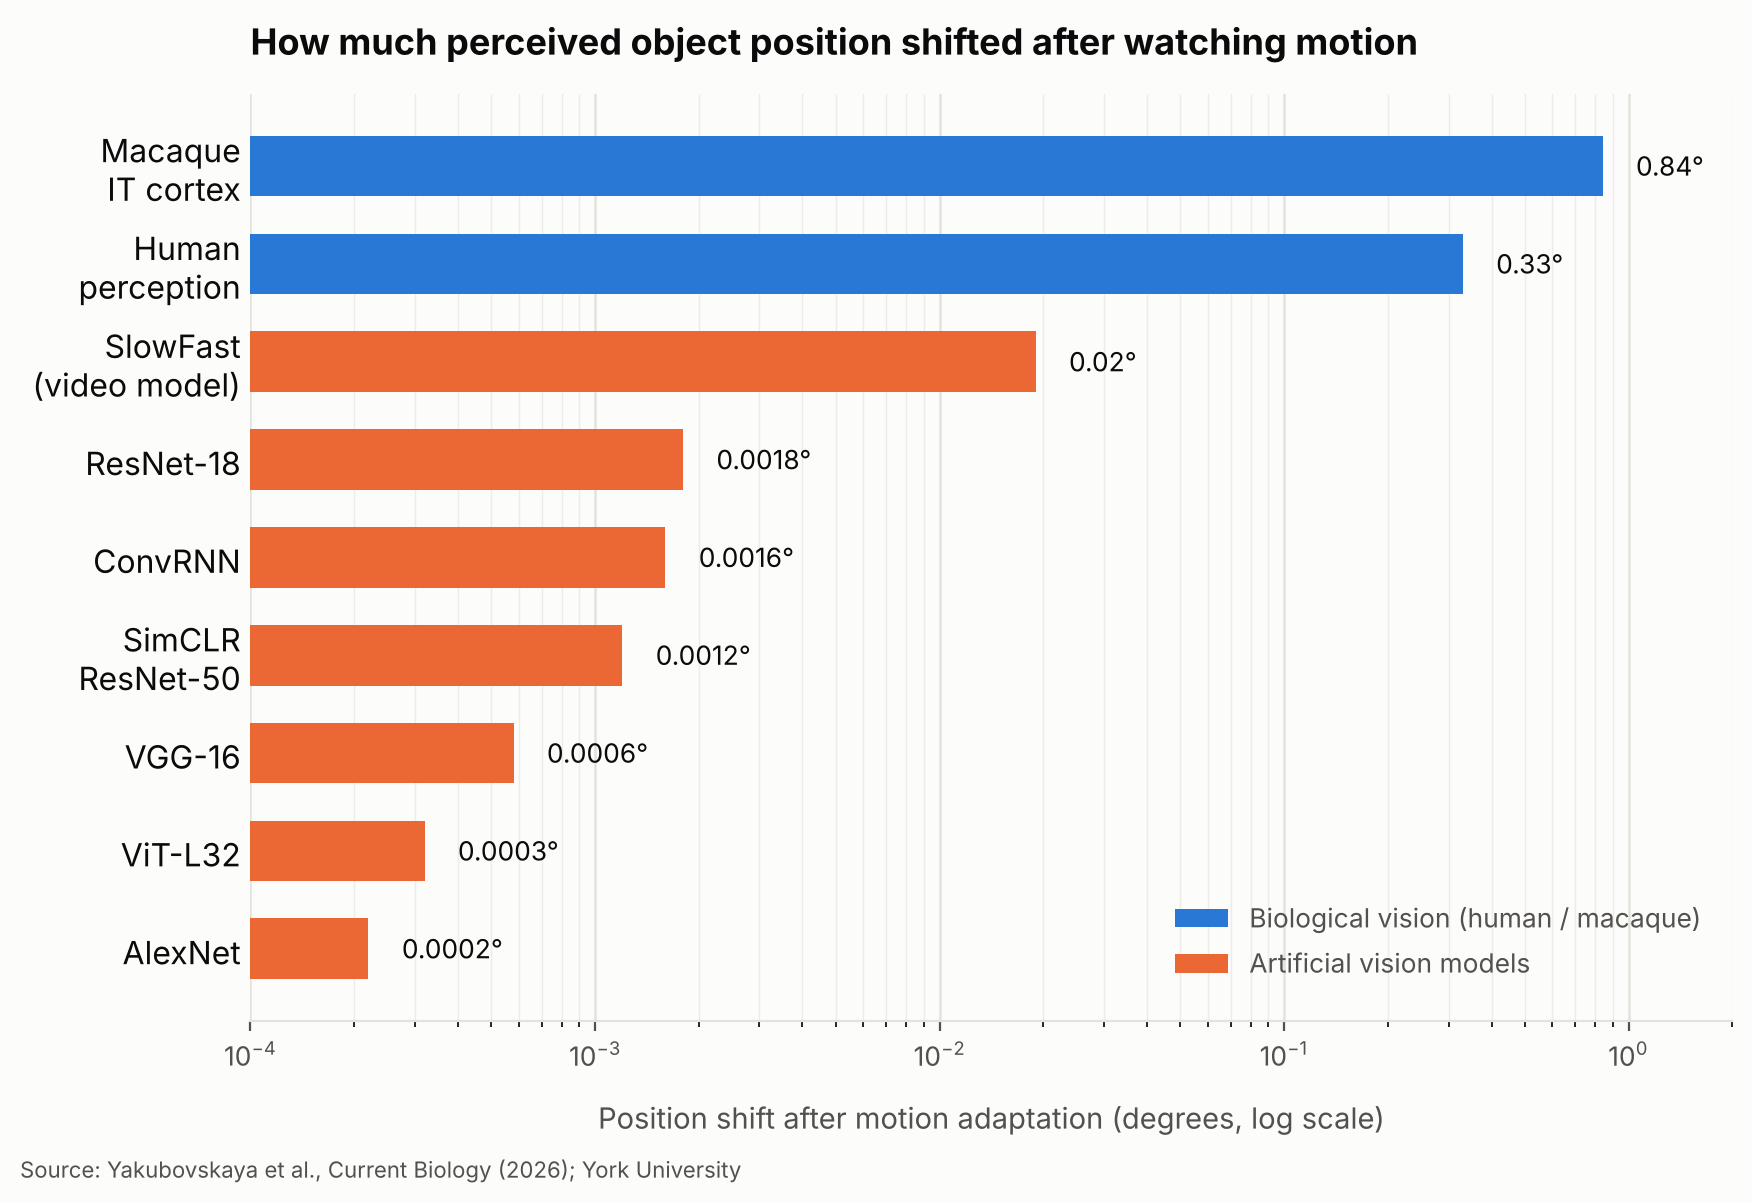
    On ordinary, non-adapted images, both the brain recordings and the AI models could track an object’s true horizontal position: linear readouts from several of the networks correlated with true position about as strongly as readouts from the monkeys’ own IT neurons did, in the range of roughly 0.59 to 0.84. So the models were not simply bad at locating objects. The difference showed up only after adaptation. Human volunteers reported an object’s position shifted by an average of 0.33 degrees of visual angle, opposite the direction of the preceding motion. The position decoded from the monkeys’ IT population activity shifted even further, by 0.84 degrees in the same direction, though that neural shift is a decoded signal rather than a direct report of what the animal consciously saw. Every AI model tested, including SlowFast, shifted by two-hundredths of a degree or less, in practice no meaningful shift at all.

    Human observers reported their perception shifting by 0.33 degrees after watching motion, and the position decoded from monkeys’ IT neurons shifted by 0.84 degrees — while every AI vision model tested shifted by two-hundredths of a degree or less.
    Bar chart comparing object-position shift after motion adaptation across human perception, macaque IT cortex, and seven AI vision models, on a log scale in degrees.
    Source: created based on data from Yakubovskaya et al., Current Biology (2026).

    Copying the Brain’s Adaptation Trick

    The gap did not mean the AI models were incapable of representing position-shifting information at all. When the researchers applied a mathematical transformation, derived from how IT neurons’ responses changed during adaptation, directly onto the models’ internal feature representations, the models began producing human-like position shifts. That shows the models’ feature spaces can support the effect once an appropriate transformation is imposed from outside. It does not show that any of the networks learned to generate that adaptation on their own during ordinary training, which is the gap the authors highlight. This is not the first time researchers have argued that borrowing the brain’s own computations, not just its final answers, could inform AI design; a separate study on how the brain re-files decision options made a related case for mining neural codes rather than just outputs.

    A Gap Worth Testing, Not Yet a Flaw

    The researchers are careful to frame this as a demonstrated difference in representations, not proof that AI vision performs worse in practice. Still, they argue it is a difference worth testing. Self-driving cars, delivery robots, and surveillance systems all judge where things are from a stream of frames in which recent motion could, in principle, matter. Consider a robot tracking a cyclist crossing its camera’s field of view: researchers could test whether the robot’s position estimate shifts the way a human’s perception would after similar recent motion, even though the current image alone has not changed. The York study does not show that reproducing this illusion would make such a system safer or more accurate; it offers a concrete, repeatable way to ask the question. Kar has argued more broadly that judging AI only by whether it reaches the right final answer can miss gaps like this one, and that matching the computations behind human perception, not only matching outputs, may help researchers evaluate whether an AI vision system handles a changing scene the way people expect.

    What the Study Doesn’t Yet Show

    The authors are explicit about the limits of their work. The experiments involved only two macaques and one specific illusion, so it is unclear how far the pattern generalizes to other forms of perceptual adaptation, to more animals, or to other stages of the visual pathway beyond IT cortex. The AI models tested were standard research networks for image and video recognition, not the newer multimodal AI assistants that combine vision with language, which the study did not evaluate. The researchers also do not claim that the perceptual bias they measured is actually beneficial for tracking objects in everyday life, only that it reflects a real computation in primate vision that current AI architectures do not reproduce on their own. They suggest the motion aftereffect could now serve as a simple, repeatable benchmark that other labs and companies use to test how their own vision models handle a changing visual world, and Kar’s group is already pursuing that direction, building what it calls more primate-like artificial neural networks for tasks such as continuous object tracking.

    Sources: Yakubovskaya et al., “The macaque IT cortex but not current artificial vision networks encode object position in perceptually aligned coordinates,” Current Biology (2026), Yakubovskaya et al., arXiv preprint (2026), York University press release coverage, via Neuroscience News

  • A Cancer Drug Already Tested in Patients Was Mainly Hitting a Different Target Than Scientists Thought — And That Could Open a New Path for Brain Cancer Treatment

    A Cancer Drug Already Tested in Patients Was Mainly Hitting a Different Target Than Scientists Thought — And That Could Open a New Path for Brain Cancer Treatment

    • A drug already tested in cancer patients turns out to work mainly by blocking a different target than scientists believed — a mix-up that could change how its past and future trials are read.
    • Researchers at the University of Sydney were testing whether the drug, called zavondemstat, could also work against glioblastoma, a particularly hard-to-treat brain cancer, when its effects stopped matching its supposed target, a protein family called KDM4.
    • Using brain-tumor cells grown from patients, genetic tricks, and detailed chemistry, the team traced the drug’s real effect to an enzyme called DHODH, which fast-growing cancer cells need to build new DNA.
    • The work is still confined to lab-grown cells and mice, not patients, but it also points to a possible new treatment route for glioblastoma, since other drugs that block the same enzyme already exist.

    Most new cancer drugs are designed around a specific molecular target: a protein that, when blocked, is expected to slow or stop tumor growth. But a study published on October 6, 2026 in Nature Chemical Biology by a University of Sydney-led team shows that an experimental drug already tested in cancer patients may owe most of its power to a completely different target than the one it was built for. The discovery does not mean the drug fails to work — it still slows cancer growth in the lab and in mice. What changed is the explanation for why, and that explanation matters for how the drug’s clinical trials — past and future — are designed and interpreted.

    A drug built for other cancers, tested against a tougher one

    The drug at the center of the study is called zavondemstat. It has already been tested in a phase 1 clinical trial of 30 patients with advanced, heavily pretreated solid tumors — about 40% of them colorectal cancer, along with prostate, pancreatic, and several other cancer types. Roughly 44% of the patients who could be evaluated had their disease stay stable on the drug, including a few who stayed stable for six months or more, and reported side effects were mild. The trial’s sponsor chose to halt the study early for business reasons before testing higher doses, so what comes next for zavondemstat is not yet settled. The drug was developed to block a family of proteins called KDM4, which many tumors produce in excess to help themselves grow and spread. A closely related laboratory compound, QC6352, has been widely used by researchers as a tool for studying what KDM4 does inside cells.

    A team led by Professor Lenka Munoz at the University of Sydney’s Charles Perkins Centre, working with collaborators at Goethe University, the University of Oxford, and the Institute of Cancer Research in London, wanted to see whether zavondemstat or QC6352 could also help against glioblastoma. Glioblastoma is the most common malignant brain tumor in adults and one of the hardest cancers to treat, so researchers routinely test whether drugs built for other cancers might also work against it.

    The target did not add up

    QC6352 showed strong activity against glioblastoma stem cells — tumor cell populations, grown from patient samples, that have stem-cell-like properties and are thought to drive the cancer’s growth and resistance to treatment. It blocked their growth at very low concentrations in lab dishes, while normal human brain support cells kept growing almost normally even at roughly ten times that concentration. That looked like confirmation that blocking KDM4 was the key to the effect. But when the researchers tested other drugs that block KDM4 just as strongly, those drugs failed to reproduce QC6352’s cancer-slowing effect. If KDM4 were really the main target, a different KDM4 blocker should have worked about as well. It did not, and that mismatch was the first sign that something else was going on.

    Tracing the main target: an enzyme called DHODH

    To find the true cause, the team ran a series of genetic and chemical tests. One enzyme kept coming up: DHODH, short for dihydroorotate dehydrogenase. DHODH helps cells manufacture pyrimidines, chemical building blocks that cells assemble into the nucleotides needed to make new DNA and RNA. Fast-dividing cancer cells depend heavily on a steady supply of these building blocks, so blocking DHODH can slow their growth sharply.

    Two lab experiments made the case convincingly. First, the researchers added extra uridine, a related building block that cells can absorb directly and use to bypass a blocked DHODH; this restored the cells’ growth despite the drug still being present, which is a sign that DHODH, not KDM4, was what the drug was really acting through. Second, when they engineered cancer cells to carry a version of DHODH that the drug could not grab onto, those cells also kept growing normally even with the drug present. Both are standard laboratory rescue experiments, not something that could be done safely in a patient, but together they pointed squarely at DHODH as the main driver of the anti-cancer effect.

    The chemistry backs this up. In a test-tube enzyme assay, QC6352 blocked DHODH at a concentration of about 0.3 nanomolar — an extremely small amount — which is in the same range as drugs built specifically to target DHODH, such as brequinar (2.6 nanomolar) and BAY2402234 (1.1 nanomolar). A true KDM4-only inhibitor called ML324, by contrast, barely touched DHODH at all even at concentrations over a thousand times higher. These numbers describe how tightly each compound grabs the enzyme in a dish, not how well it would work in a patient, but the gap between QC6352 and ML324 is the clearest sign that QC6352’s anti-cancer effect runs mainly through DHODH. The researchers now describe zavondemstat and QC6352 as “dual KDM4–DHODH inhibitors”: both targets are blocked, but the DHODH side appears to be doing most of the work against glioblastoma.

    Schematic diagram comparing the assumed drug pathway through KDM4 with the pathway the study found through DHODH
    Scientists assumed the drug worked mainly by blocking KDM4 (top). The study found it mainly works by blocking DHODH instead (bottom). Schematic illustration, not an accurate depiction of real molecular structures.
    Bar chart comparing DHODH-blocking potency of QC6352, BAY2402234, brequinar, and ML324
    In a test-tube enzyme assay, QC6352 blocked DHODH about as strongly as drugs designed specifically for that purpose, while a KDM4-only drug barely blocked it at all. Data: Sterling et al., Nature Chemical Biology (2026).

    Why this matters beyond the lab

    QC6352 has been used as a standard research tool in laboratories around the world to study what KDM4 does. If much of its effect actually comes from DHODH, some of those earlier studies may need to be re-examined, since what looked like evidence about KDM4 biology could instead reflect DHODH biology.

    There is a more immediate concern, too. Zavondemstat has already been given to patients in a clinical trial that was designed and interpreted around the idea that it works mainly through KDM4. Professor Munoz has pointed out that getting a drug’s mechanism wrong is not just a historical curiosity — it can lead to poorly designed trials, choosing the wrong patients to enroll, and wasted research effort, and she argues this kind of mix-up is still common in cancer drug development today. To help avoid repeating the problem, her team also designed new experimental compounds that block KDM4 without touching DHODH at all, giving future researchers cleaner tools to study KDM4 on its own.

    A possible upside for brain cancer patients

    The mix-up also comes with a possible silver lining. In mice carrying human glioblastoma tumors, QC6352 extended median survival from 28.5 days to 34.5 days — an absolute difference of six days, or about 20% longer than in untreated mice — while normal brain support cells tolerated roughly ten times the dose without obvious harm in lab tests. That is an early signal of activity in animals, not evidence of a survival benefit in people. Still, because several drugs that block DHODH already exist and are being studied for other cancers, this discovery could give researchers a head start on exploring DHODH-targeted treatment for glioblastoma specifically, rather than starting drug development from zero. Much work would still be needed to show that an existing DHODH inhibitor can reach brain tumors at a safe dose and actually help patients.

    In mice, blocking the enzyme DHODH with QC6352 stretched median survival from 28.5 to 34.5 days — six days, or about 20% longer than no treatment at all.

    It is worth being careful about how far this points, though. The findings so far come only from lab-grown cells and mice, not from glioblastoma patients, and zavondemstat’s one completed human trial was not designed with DHODH in mind. Researchers elsewhere are also exploring other ways to make cancer treatment more targeted and less damaging to healthy tissue, such as an approach that gets cancer cells to manufacture their own chemotherapy drug while sparing normal cells. The DHODH finding adds another option to that broader search: not a cure in hand, but a clearer, evidence-based reason to try a treatment path that already has other drugs ready to test.

    Sources: University of Sydney, Nature Chemical Biology